# Module 4: PrognosiX Extended Workflow
This extended `PrognosiX` workflow reflects the package's newer prognosis capabilities and supports full clinical prognostic-model development and validation. It adds competing risks, time-dependent ROC comparison, multi-time calibration, repeated cross-validation, C-index comparison, Bayesian tuning, AIC-guided selection, overall calibration, external-validation diagnostics, and deployment.
## Execution Notes
This workflow is computationally intensive and uses optional packages that are checked only when their methods are requested. Verify paths, outcome definitions, prediction horizons, the output root, and dependencies before running. Keep development and validation independent throughout, report uncertainty with point estimates, and distinguish exploratory comparisons from prespecified confirmatory analyses.
## Step-by-step Workflow
The workflow is divided into short stages. Each note explains the purpose, key checks, and interpretation limits. Generated plots and tables appear directly below their code chunk.
### About this chapter
**Audience.** Users who already have a working PrognosiX pipeline and want the ten production extensions on top of it.
**Input.** Reads `data/PMID37633276_DIA_plasmaproomic.xlsx` (sheet `Table S1B`) directly.
The chapter runs end to end as one session:
1. **Environment and configuration**
2. **Data preparation (move time/status to info.data)**
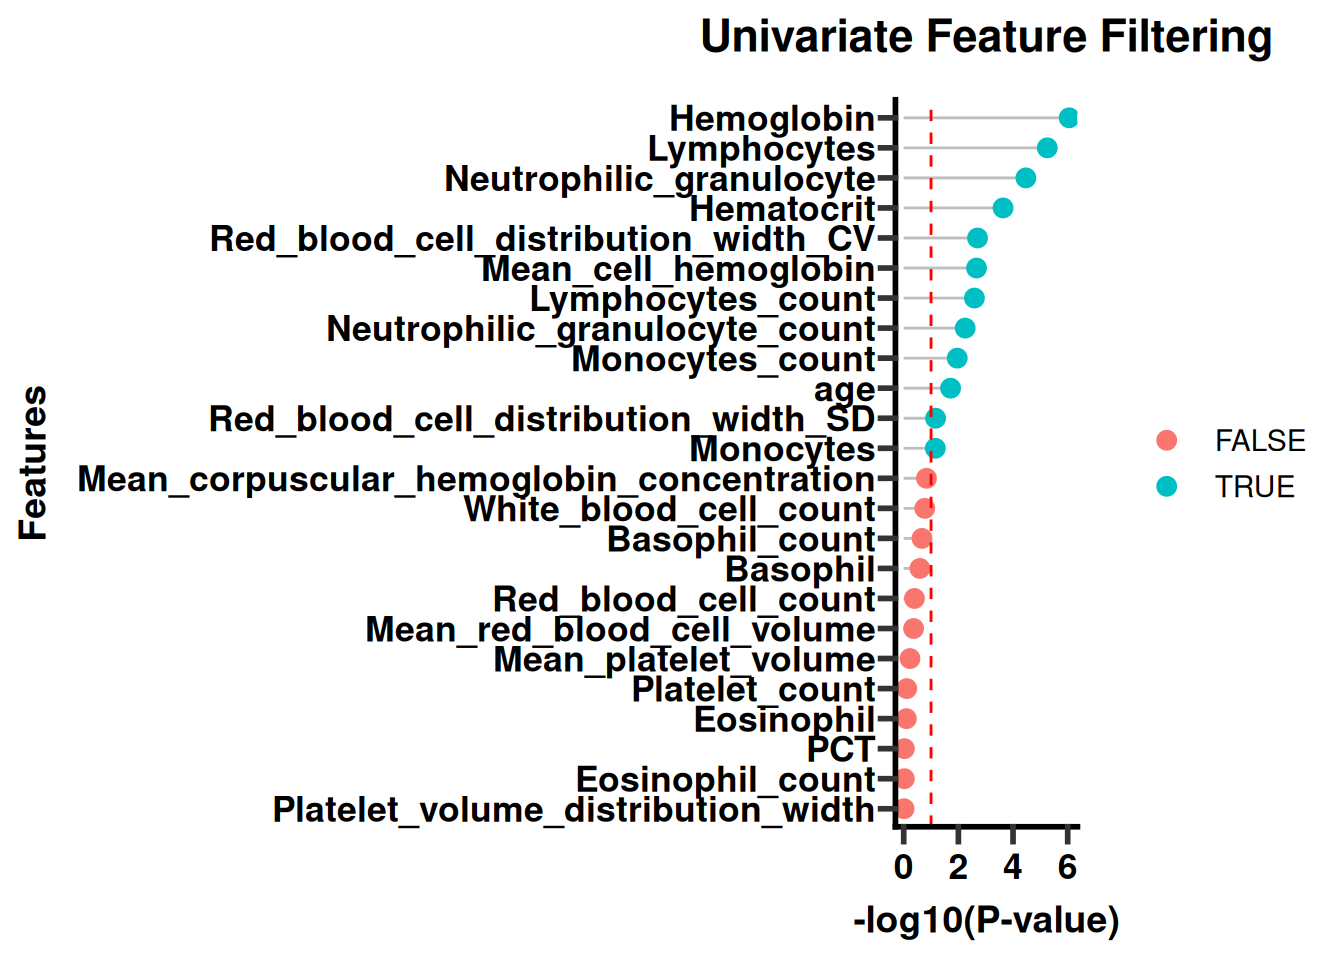
3. **Feature selection (ONLY on training set)**
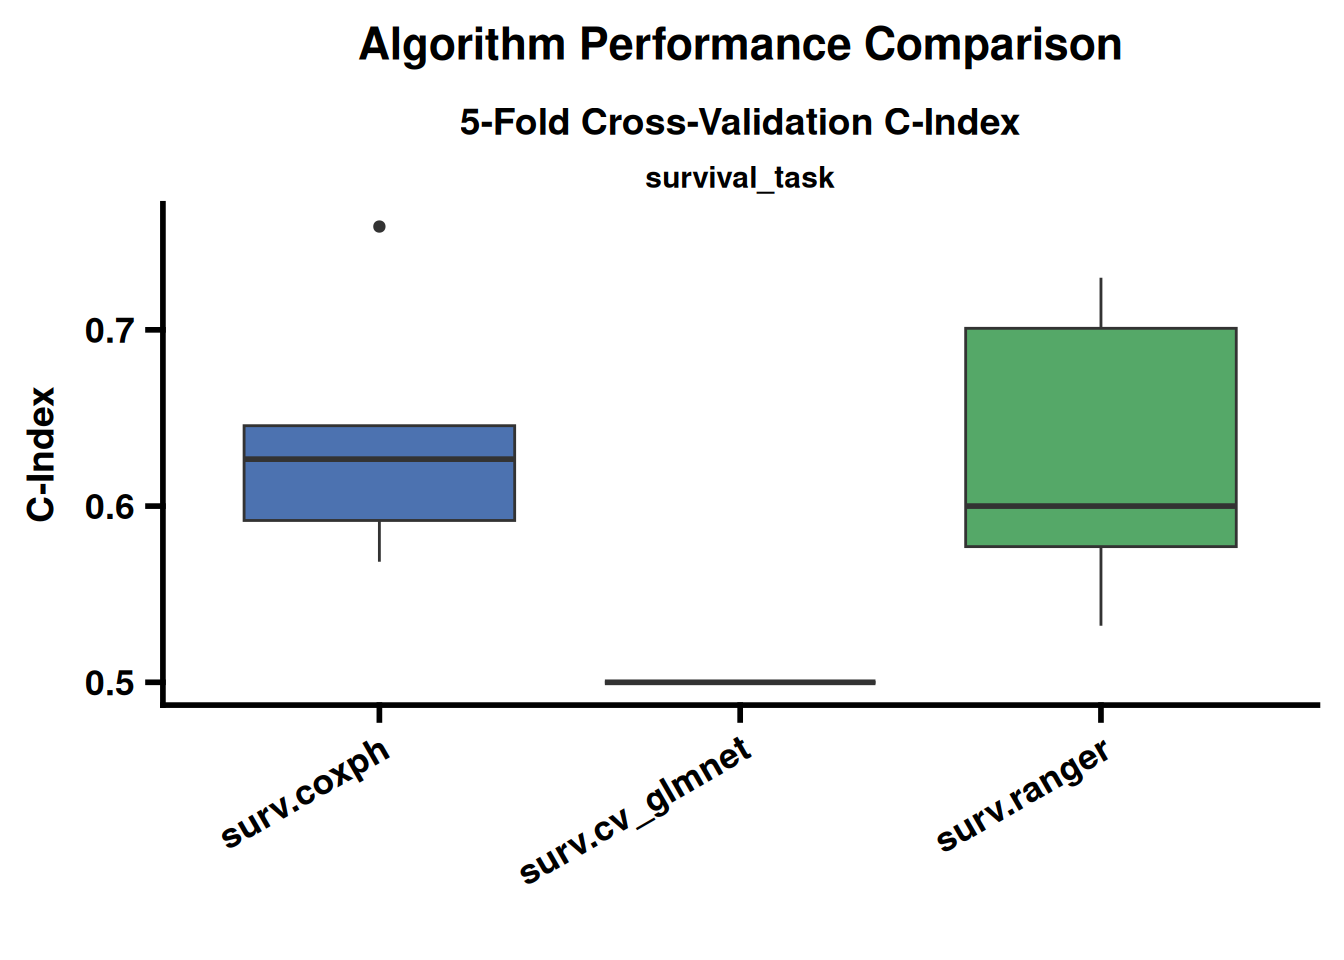
4. **Algorithm benchmarking and hyperparameter tuning**
5. **Core model evaluation**
- **Feature stability (LASSO bootstrapping)**
- **Feature ablation (drop each feature and measure C-index drop)**
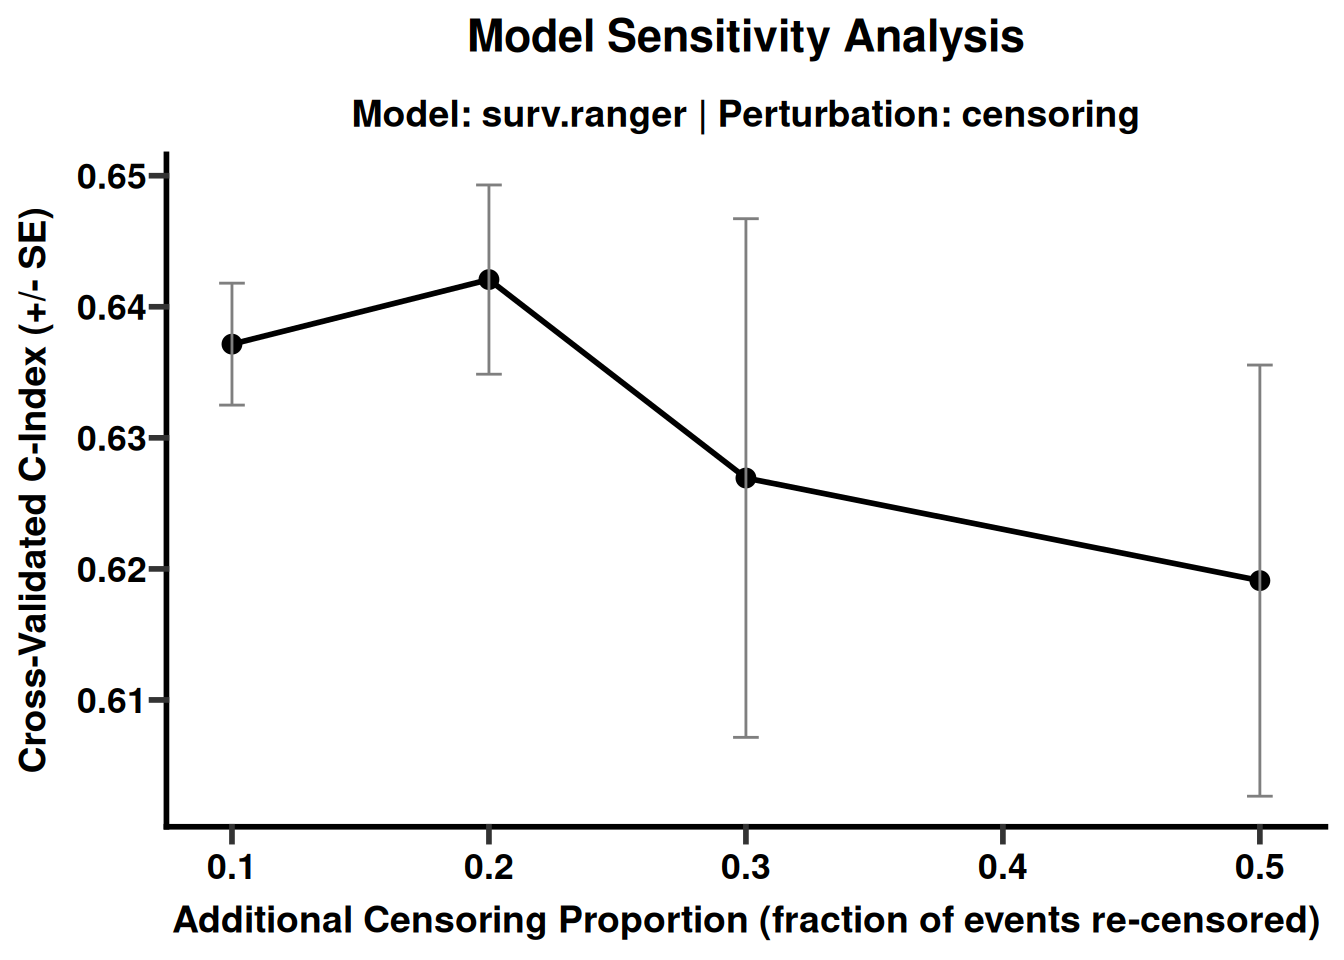
- **Model sensitivity (sample size and censoring rate)**
6. **Decision curve analysis (DCA) and SHAP explanations (on validation set)**
7. **Ten advanced extensions (all executed sequentially)**
8. **Save final PrognosiX object and deploy**
9. **Final report**
### 0 Environment and configuration
This section defines seeds, output paths, and dependencies. Update these paths and key parameters first when using new data.
````{r}
#| label: module4-pro-12
#| cache: false
#| echo: true
#| message: false
#| warning: false
#| fig-show: hold
#| out-width: '100%'
# 0. Environment and configuration
# ---------------------------------------------------------------------------
set.seed(2025)

# Version and output root
VERSION <- "Advanced_extensions"
OUTPUT_ROOT <- "./PrognosiX_Output"
OUTPUT_DIR <- file.path(OUTPUT_ROOT, VERSION)

# Load required packages
library(icare)
required_pkgs <- c("mlr3", "mlr3proba", "mlr3viz", "mlr3learners",
                   "survival", "survminer", "ggplot2", "caret", "dplyr",
                   "tidyr", "rms", "risksetROC", "survex", "dcurves",
                   "readxl", "patchwork", "ggrepel", "maxstat")
missing_pkgs <- required_pkgs[!sapply(required_pkgs, requireNamespace, quietly = TRUE)]
if (length(missing_pkgs)) install.packages(missing_pkgs)
invisible(lapply(required_pkgs, library, character.only = TRUE))

# Register OUTPUT_DIR with the package rather than defining a local sub_dir().
# icare already ships sub_dir(); a local definition shadows it only inside this
# script, so functions INSIDE the package that call sub_dir() themselves (e.g.
# plot_tdROC_comparison(), plot_multitime_calibration(), plot_clinical_impact())
# would still resolve it in the icare namespace and write to a session-temp
# directory. Calling set_output_root() points both at the same tree.
set_output_root(OUTPUT_DIR)

# Create version root and standard subfolders
sub_dir()
sub_dir("data")
sub_dir("01_feature_selection")
sub_dir("02_model")
sub_dir("03_evaluation")
sub_dir("04_robustness")
sub_dir("05_xai")

# Additional packages for extensions (checked inside each function)
ext_pkgs <- c("mlr3extralearners", "survcomp", "mlr3mbo", "bbotk", "MASS", "glmnet")
for (pkg in ext_pkgs) {
  if (!requireNamespace(pkg, quietly = TRUE)) {
    message("Note: Package '", pkg, "' not installed. Some advanced extensions may be skipped.")
  }
}

# ---------------------------------------------------------------------------
````
### 1 Data preparation (move time/status to info.data)
This section imports and organizes the data. Check dimensions and variable coding before continuing.
````{r}
#| label: module4-pro-13
#| cache: false
#| echo: true
#| message: false
#| warning: false
#| fig-show: hold
#| out-width: '100%'
# 1. Data preparation (move time/status to info.data)
# ---------------------------------------------------------------------------
raw_dis <- as.data.frame(read_excel("data/PMID37633276_DIA_plasmaproomic.xlsx", sheet = "Table S1B"))
raw_dis <- raw_dis[!grepl(x = raw_dis$`Case ID`, pattern = "^KC"), ]

# Extract numeric features (laboratory parameters)
mat <- raw_dis[, c("White blood cell count",
                   "Lymphocytes%", "Monocytes%", "Neutrophilic granulocyte%", "Eosinophil%",
                   "Basophil%", "Lymphocytes count", "Monocytes count", "Neutrophilic granulocyte count",
                   "Eosinophil count", "Basophil count", "Red blood cell count",
                   "Hemoglobin", "Hematocrit", "Mean red blood cell volume", "Mean cell hemoglobin",
                   "Mean corpuscular hemoglobin concentration", "Red blood cell distribution width CV",
                   "Red blood cell distribution width SD", "Platelet count", "Mean platelet volume",
                   "PCT", "Platelet volume distribution width")]

index <- grepl(x = raw_dis$`Case ID`, pattern = "^HC")

# Clinical metadata (including time, status, and subgroup variables)
inf <- raw_dis[, c("Case ID", "Sample type", "Plasma proteome ID", "Tissue proteome ID",
                   "Gender", "Age at diagnosis", "Tobacco smoking history", "Drinking history",
                   "Vital status", "Days to last followup", "Days until death",
                   "Combined days to last followup or death", "Progressive-free survival_Status",
                   "Progressive-free survival_Months", "Tumor location", "Tumor size (cm)",
                   "T-category", "Lymph node involvement", "Distant metastasis",
                   "TNM Stage", "Grade", "Morphology")]

# The group label lives in `inf` ONLY -- see the Module 1 chapter for why.
inf$group <- factor(ifelse(index, "Healthy Control", "Case"),
                    levels = c("Healthy Control", "Case"))
mat <- as.matrix(mat)
storage.mode(mat) <- "numeric"

rownames(mat) <- inf$`Case ID`
rownames(inf) <- inf$`Case ID`
mat <- as.data.frame(mat)
mat$age <- inf$`Age at diagnosis`
mat$sex <- inf$Gender

inf$time <- inf$`Combined days to last followup or death`
inf$event <- inf$`Vital status`
inf$event <- ifelse(inf$event == "Dead", 1, 0)

# Keep only disease samples (compare the label text, not a code -- the group
# column is a factor, so `== 1` would silently match nothing)
inf <- inf[inf$group == "Case", ]
mat <- mat[rownames(inf), ]
mat$time <- inf$time
mat$status <- inf$event

# Build Stat object with clean.data (features) and info.data (metadata including time/status)
stat_obj <- CreateStatObject(
  clean.data = mat,
  info.data = inf,
  group_col = "group",
  na.action = "allow"
)
cat("Stat object created.\n")
# Convert to PrognosiX: time/status are moved to info.data automatically
prog <- Stat_to_PrognosiX(stat_obj, "time", "status",
                          na_action = "omit",
                          min_events = 10,
                          verbose = TRUE)
# ---------------------------------------------------------------------------
````
### 2 Feature selection (ONLY on training set)
This section selects candidate features. Consider effect size, stability, and biological plausibility rather than a single significance measure.
````{r}
#| label: module4-pro-14
#| cache: false
#| echo: true
#| message: false
#| warning: false
#| fig-show: hold
#| out-width: '100%'
# 2. Feature selection (ONLY on training set)
# ---------------------------------------------------------------------------
task_full <- surv_extract_task(prog)
n <- task_full$nrow
train_idx <- caret::createDataPartition(task_full$data()[[task_full$target_names[2]]],
                                        p = 0.7, list = FALSE)
val_idx <- setdiff(seq_len(n), train_idx)

train_task <- task_full$clone()$filter(train_idx)
val_task <- task_full$clone()$filter(val_idx)

# Multi‑method feature selection: univariate Cox, LASSO, RF importance, Ridge, Elastic Net, VIMP
methods_to_run <- c("uni_cox", "lasso", "rf_imp", "ridge", "enet", "vimp")
feat_sel <- surv_feature_selection_multi(
  object = train_task,
  methods = methods_to_run,
  p_threshold = 0.1,
  top_ratio = 0.5,
  combine = "union",
  verbose = TRUE
)
selected_feats <- feat_sel$selected
cat("Selected features:", paste(selected_feats, collapse = ", "), "\n")
write.csv(feat_sel$method_table,
          file = file.path(sub_dir("01_feature_selection"), "feature_selection_methods.csv"),
          row.names = FALSE)

train_task <- train_task$select(selected_feats)
val_task <- val_task$select(selected_feats)

# Save train/validation data for reproducibility
train_data <- as.data.frame(train_task$data())
val_data <- as.data.frame(val_task$data())
write.csv(train_data, file = file.path(sub_dir("data"), "training_data.csv"), row.names = FALSE)
write.csv(val_data,   file = file.path(sub_dir("data"), "validation_data.csv"), row.names = FALSE)

# ---------------------------------------------------------------------------
````
### 3 Algorithm benchmarking and hyperparameter tuning
This section trains and compares candidate models. Select models using discrimination, calibration, stability, and clinical utility together.
````{r}
#| label: module4-pro-15
#| cache: false
#| echo: true
#| message: false
#| warning: false
#| fig-show: hold
#| out-width: '100%'
# 3. Algorithm benchmarking and hyperparameter tuning
# ---------------------------------------------------------------------------
# Compare Cox, LASSO, and Random Survival Forest (Ranger)
learners_list <- list(
  surv_get_learner("surv.coxph",     train_task),
  surv_get_learner("surv.cv_glmnet", train_task),
  surv_get_learner("surv.ranger",    train_task)
)
bmr1 <- surv_run_algorithm_benchmark(train_task, learners_list)
bmr2 <- surv_benchmark_learners(train_task, learner_ids = c("surv.coxph", "surv.ranger"), tune = FALSE)
bmr2_summary <- surv_summarize_benchmark(bmr2)
write.csv(bmr2_summary, file = file.path(sub_dir("02_model"), "algorithm_benchmark.csv"), row.names = FALSE)

# Select the best model (here Ranger) and perform hyperparameter tuning
best_id <- "surv.ranger"
tune <- surv_train_and_tune(train_task, best_id, tuning_budget = 25)
best_lrn <- tune$learner
cv_cindex <- tune$cv_performance
cat("CV C-index after tuning:", round(cv_cindex, 4), "\n")
# Train a Cox model for comparison (used in extensions)
cox_lrn <- surv_get_learner("surv.coxph", train_task)$train(train_task)

# ---------------------------------------------------------------------------
````
### 4 Core model evaluation
This section trains and compares candidate models. Select models using discrimination, calibration, stability, and clinical utility together.
````{r}
#| label: module4-pro-16
#| cache: false
#| echo: true
#| message: false
#| warning: false
#| fig-show: hold
#| out-width: '100%'
# 4. Core model evaluation
# ---------------------------------------------------------------------------
# Warning: if no independent validation data is provided, some metrics are apparent
if (is.null(val_data)) {
  msg <- paste(
    "\n",
    "==================== WARNING ====================\n",
    "No external validation data (`val_data`) provided.\n",
    "KM curves, time‑dependent AUC, and nomogram will be\n",
    "computed on the TRAINING SET – these are apparent\n",
    "(optimistic) estimates. Do not report as generalizable.\n",
    "==================================================\n"
  )
  warning(msg, call. = FALSE, immediate. = TRUE)
  message(msg)
}

# Training set (apparent) performance
best_lrn$predict_type <- "distr"
train_perf <- surv_evaluate_model(best_lrn, train_task,
                                  measures = list(msr("surv.cindex"), msr("surv.graf")))
cat("Training apparent C-index:", round(train_perf$surv.cindex, 4), "\n")
# Validation set (unbiased) performance
val_pred <- best_lrn$predict(val_task)
val_cindex <- val_pred$score(msr("surv.cindex"))
cat("Validation C-index:", round(val_cindex, 4), "\n")
# Save performance metrics
perf_df <- data.frame(
  Dataset = c("Training", "Validation"),
  C_index = c(train_perf$surv.cindex, val_cindex)
)
write.csv(perf_df, file = file.path(sub_dir("03_evaluation"), "performance.csv"), row.names = FALSE)

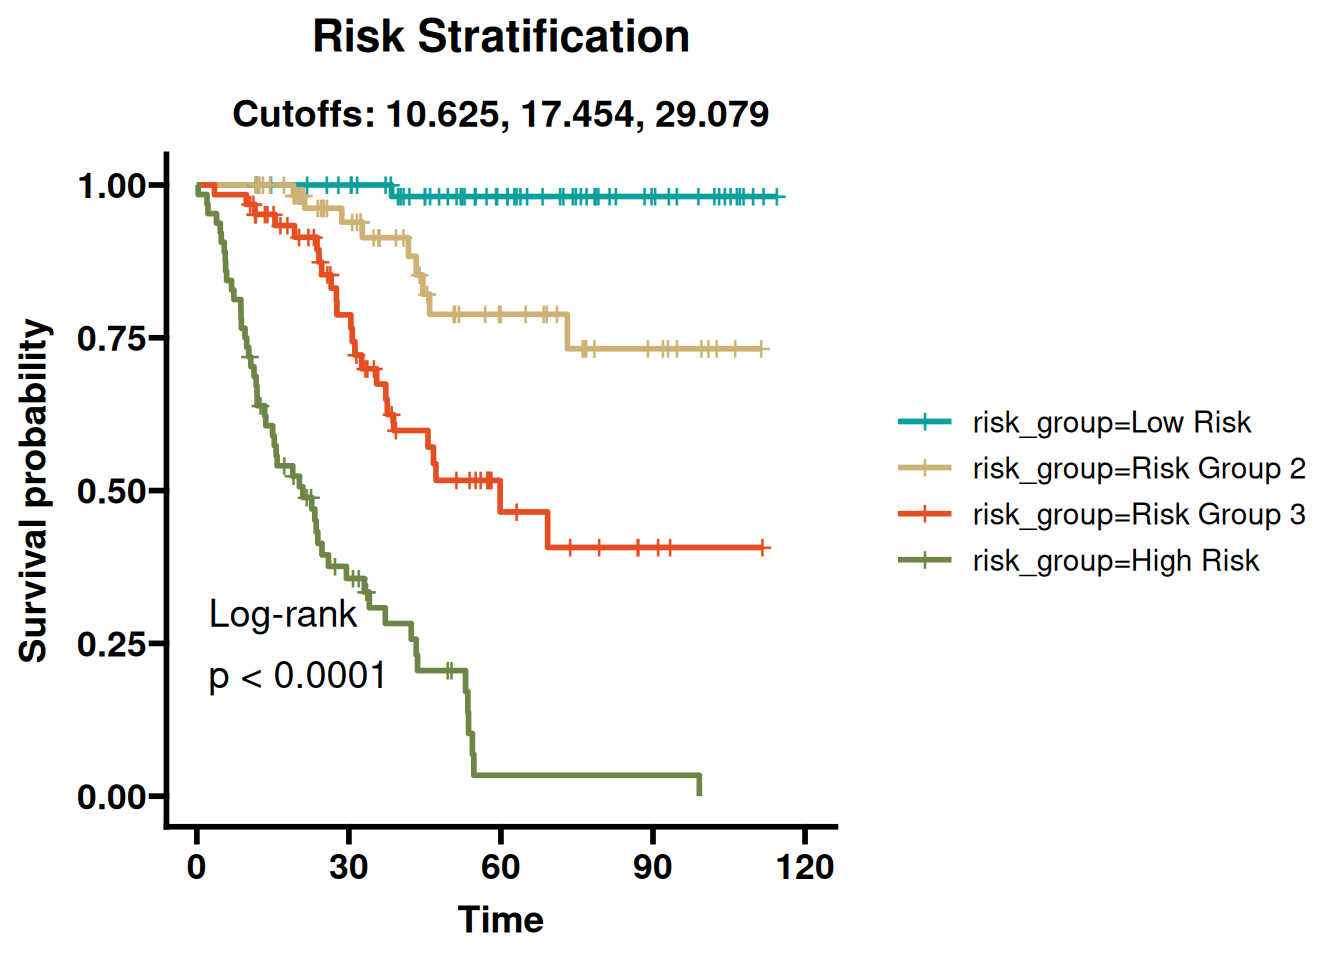
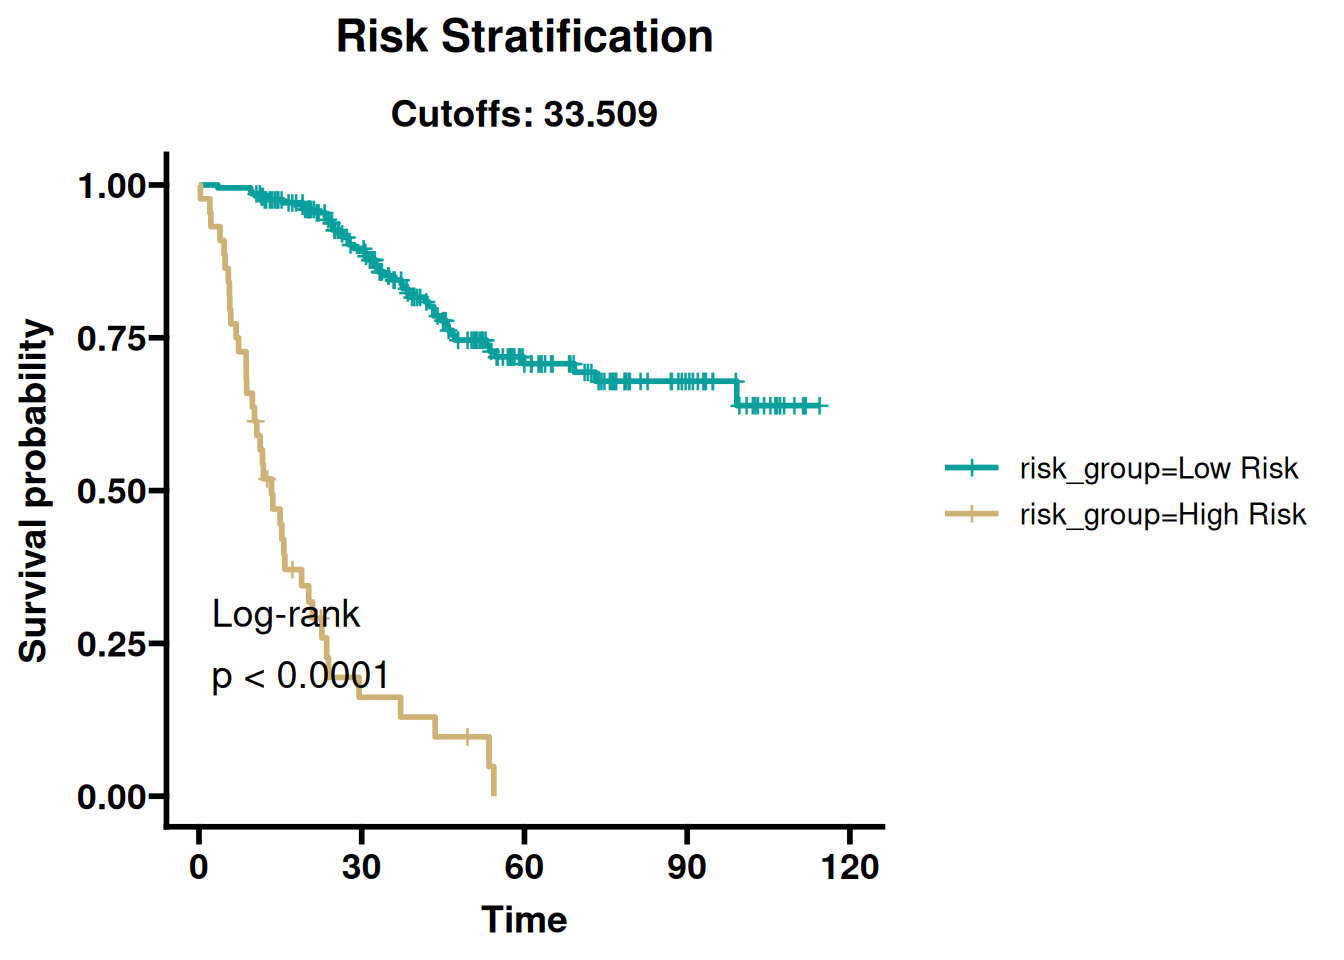
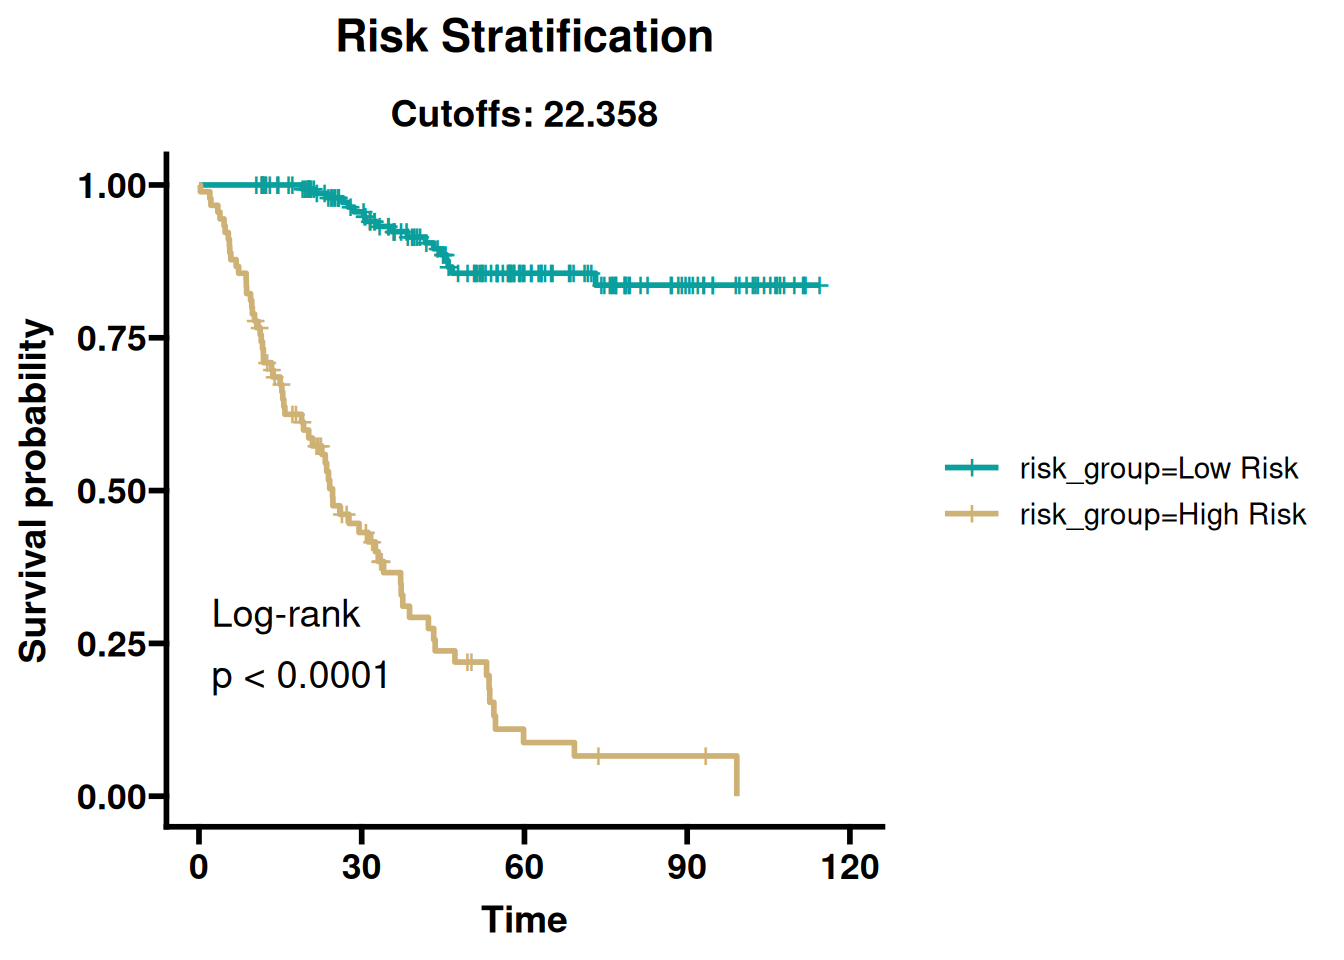
# ---- 4.1 Risk stratification KM curves (multiple cutoff methods) ----
pred_train <- best_lrn$predict(train_task)
cut_df <- as.data.frame(train_task$data())
cut_df$risk <- pred_train$crank

# Compute optimal cutoff using surv_cutpoint; fallback to median if fails
cut_res <- tryCatch({
  surv_cutpoint(cut_df, time = "time", event = "status", variables = "risk")
}, error = function(e) {
  warning("surv_cutpoint failed: ", e$message, ". Using median split.")
  list(cutpoint = data.frame(cutpoint = median(cut_df$risk, na.rm = TRUE)))
})
opt_cutoff <- cut_res$cutpoint$cutpoint
cat("Optimal cutoff (from surv_cutpoint):", round(opt_cutoff, 4), "\n")
# Generate KM plots for four cutoff methods
# p_optimize and maxstat are exploratory; their p-values should not be used as confirmatory
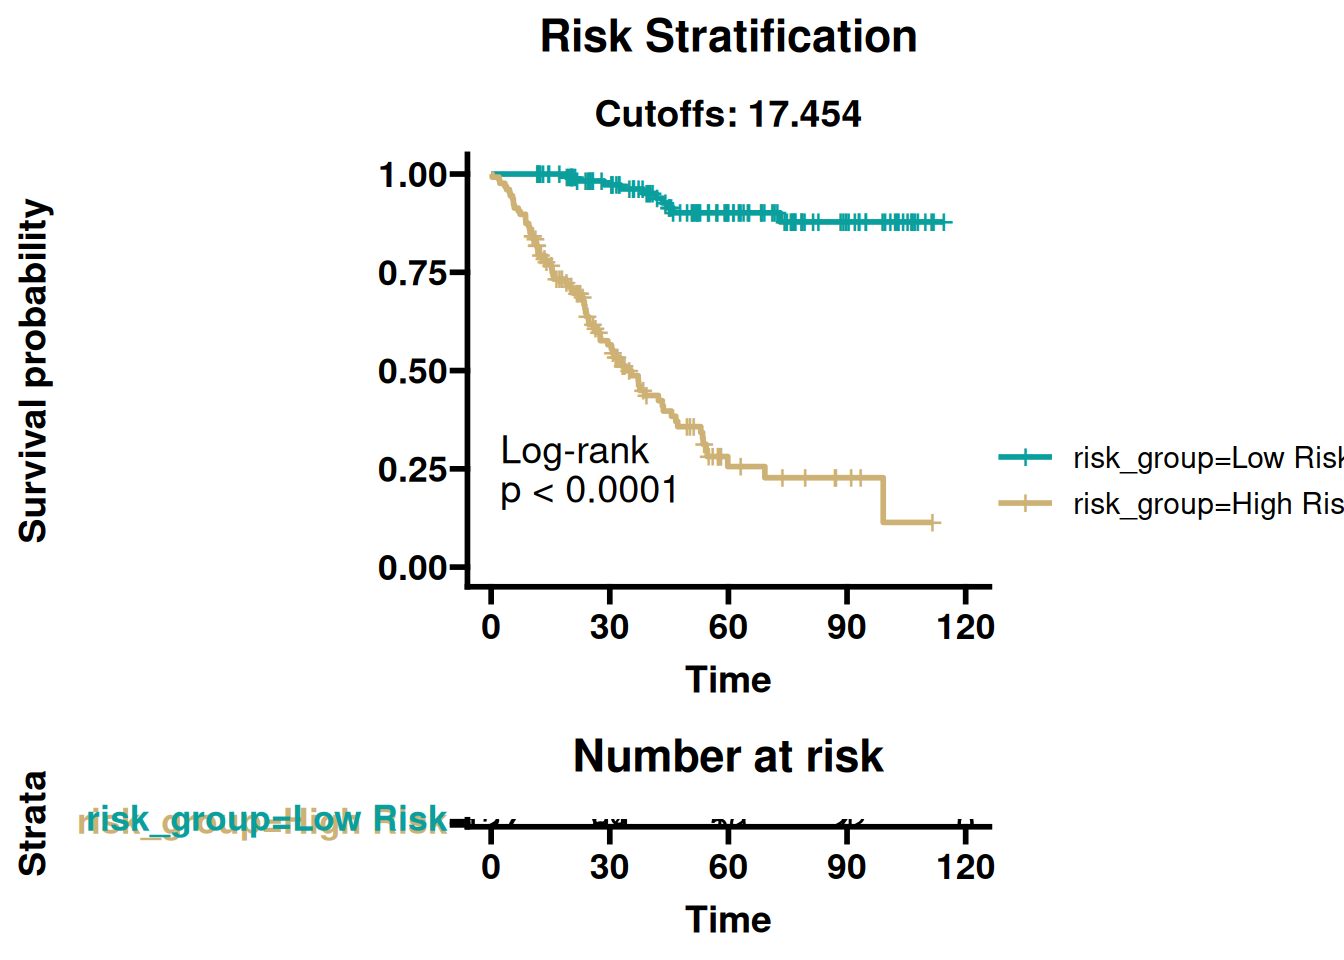
km_median    <- surv_plot_risk_km(best_lrn, train_task, "median", risk_table = TRUE)
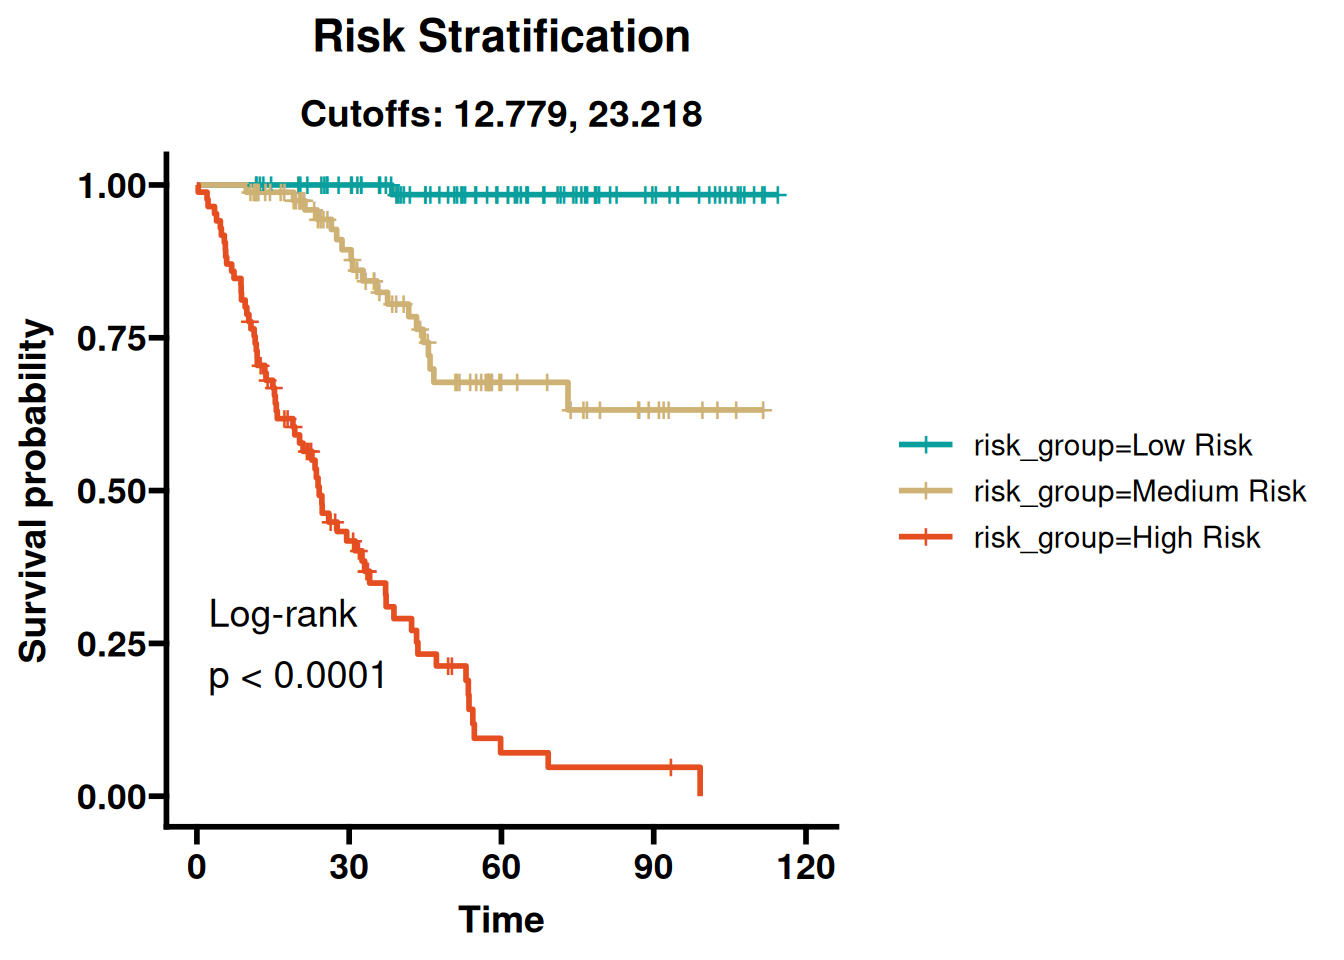
km_tertile   <- surv_plot_risk_km(best_lrn, train_task, "tertile")
km_quartile  <- surv_plot_risk_km(best_lrn, train_task, "quartile")
km_p_optimize <- surv_plot_risk_km(best_lrn, train_task, "p_optimize",
                                   n_boot = 100, fraction = 0.7)
km_maxstat   <- surv_plot_risk_km(best_lrn, train_task, "maxstat",
                                  n_boot = 100, minprop = 0.3)

# Save training KM plots

print(km_median)
print(km_tertile)
print(km_quartile)
print(km_p_optimize)
print(km_maxstat)

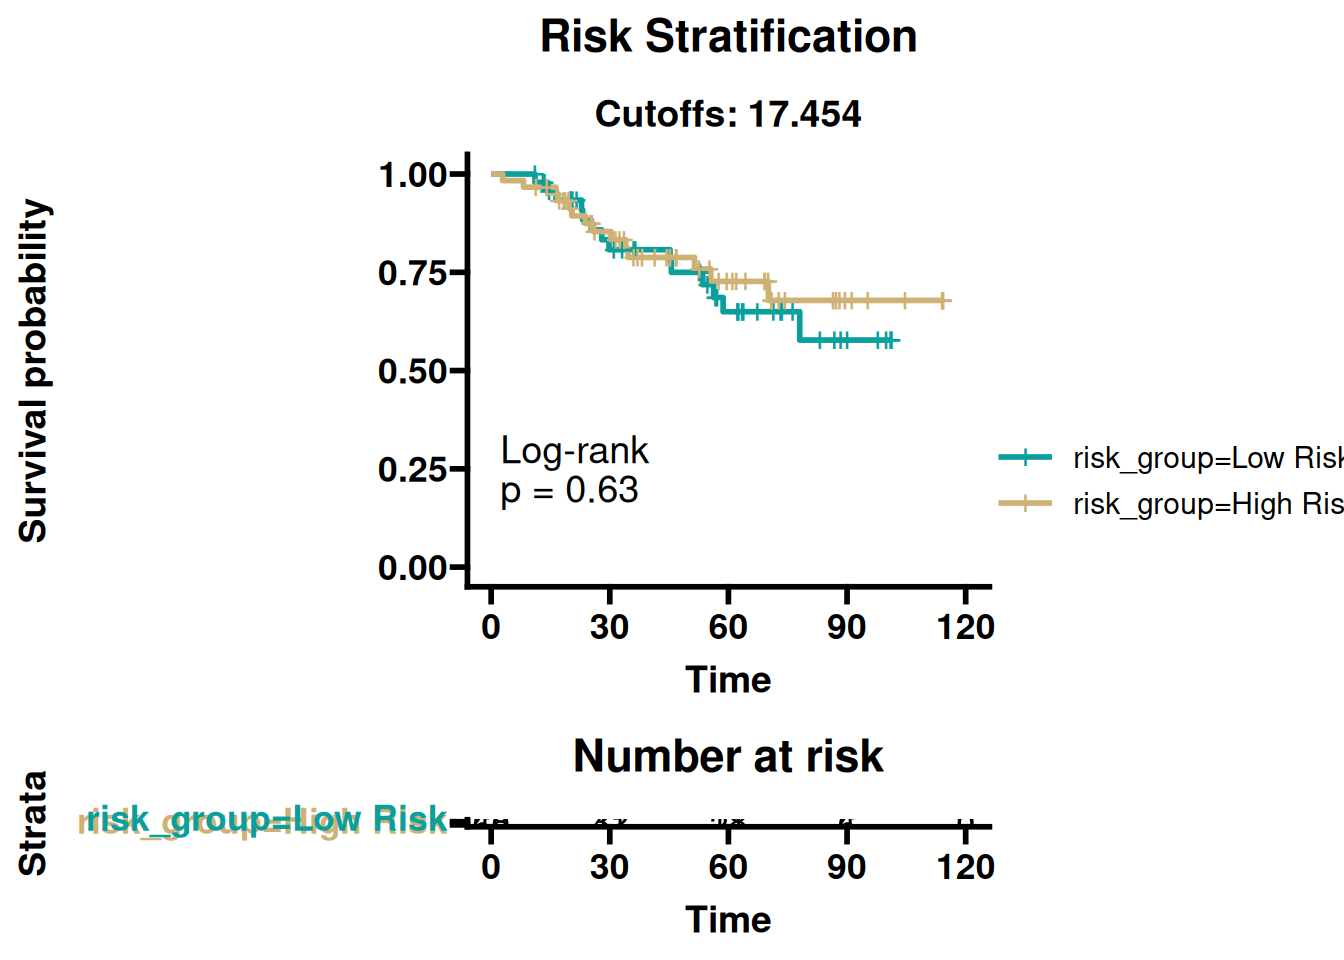
# Apply the training median cutoff to the validation set (fixed threshold)
train_cutoff <- get_cf(km_median)
if (is.null(train_cutoff)) train_cutoff <- opt_cutoff
km_val_fixed <- surv_plot_risk_km(best_lrn, val_task,
                                  cutoff_method = "custom",
                                  custom_cutoffs = train_cutoff,
                                  risk_table = TRUE)
print(km_val_fixed)

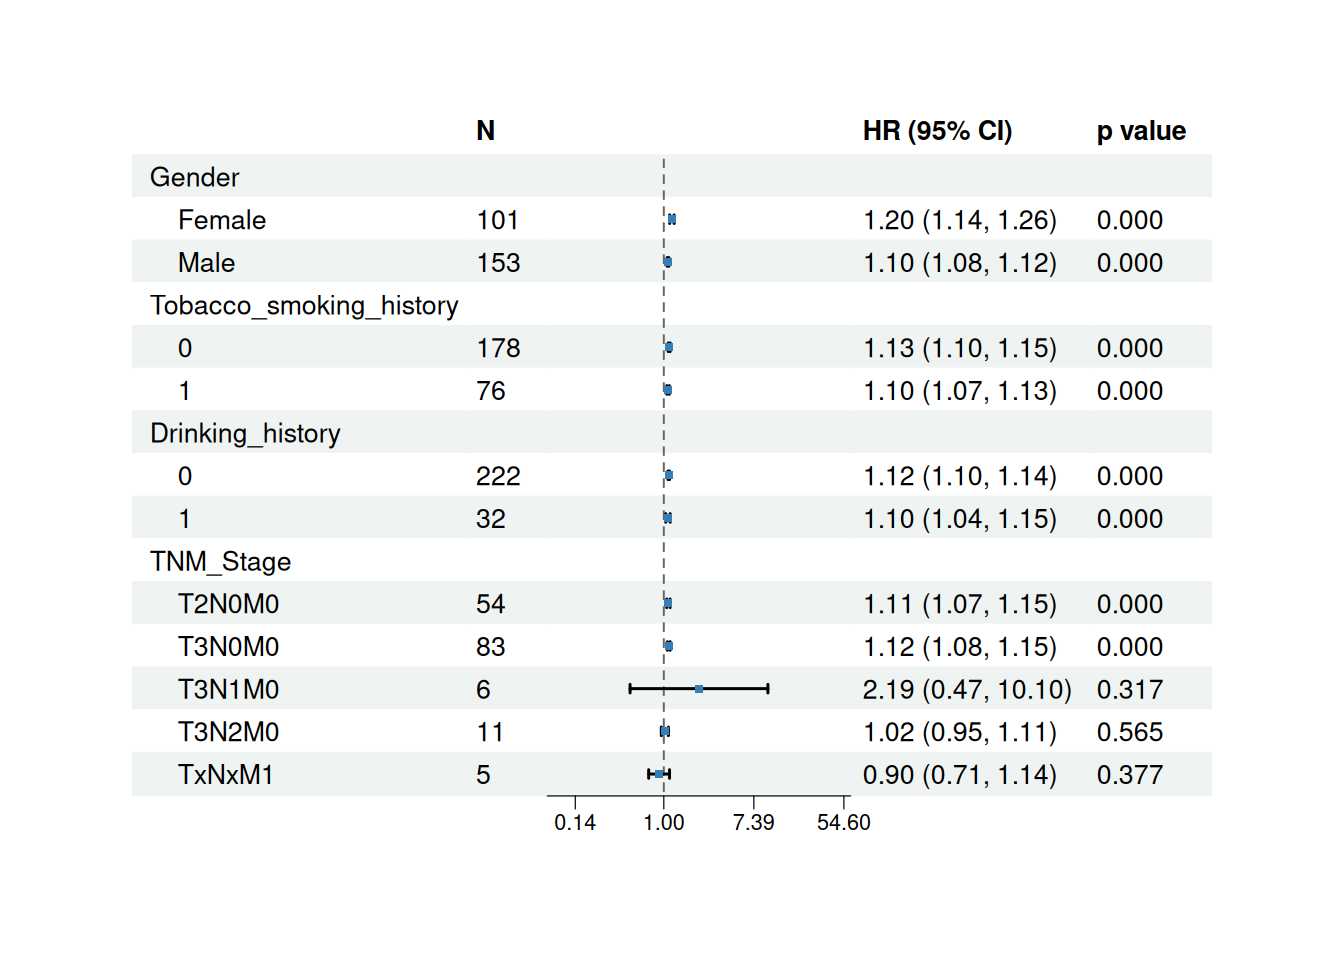
# ---- 4.2 Subgroup forest plot (using training set) ----
# Subset prog to training samples to ensure row consistency
train_prog <- prog
train_prog@clean.data <- prog@clean.data[train_idx, , drop = FALSE]
train_prog@info.data <- prog@info.data[train_idx, , drop = FALSE]
train_prog@survival.data <- prog@survival.data[train_idx, , drop = FALSE]

clinical_cols <- colnames(train_prog@info.data)
# info.data names are normalised by CreateStatObject(): spaces and dots become
# underscores. Passing the dotted spelling would make intersect() drop
# everything except "Gender" and silently shrink the subgroup forest.
candidate_vars <- c("Gender", "Tobacco_smoking_history", "Drinking_history", "TNM_Stage")
subgroup_vars <- intersect(candidate_vars, clinical_cols)

forest <- surv_plot_subgroup_forest(
  learner = best_lrn,
  object = train_task,
  subgroup_vars = subgroup_vars,
  prog = train_prog,
  save_plot = TRUE,
  save_dir = sub_dir("03_evaluation"),
  file_name = "subgroup_forest.pdf"
)
print(forest)
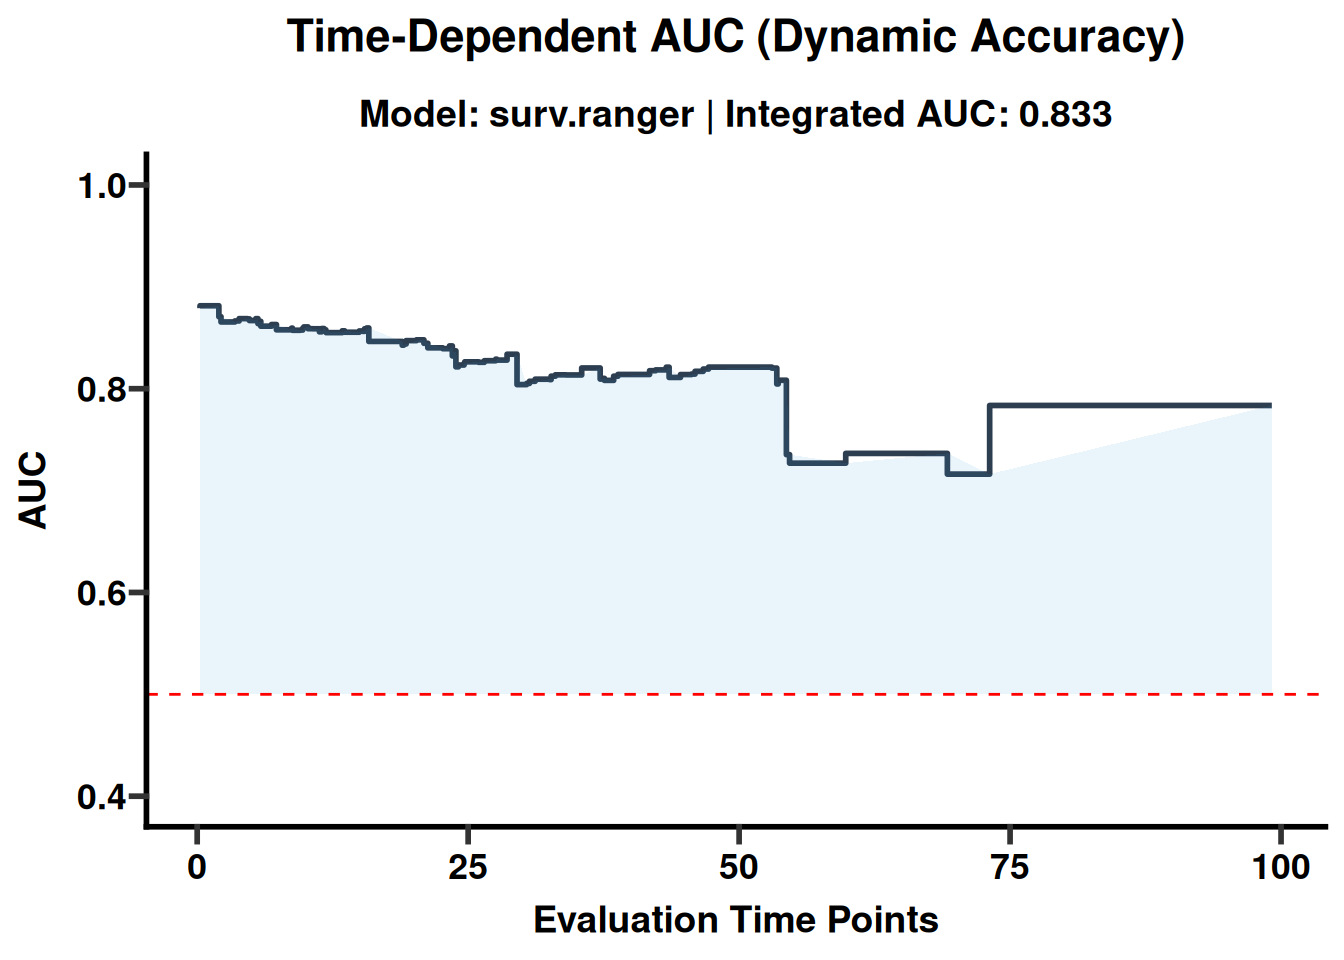
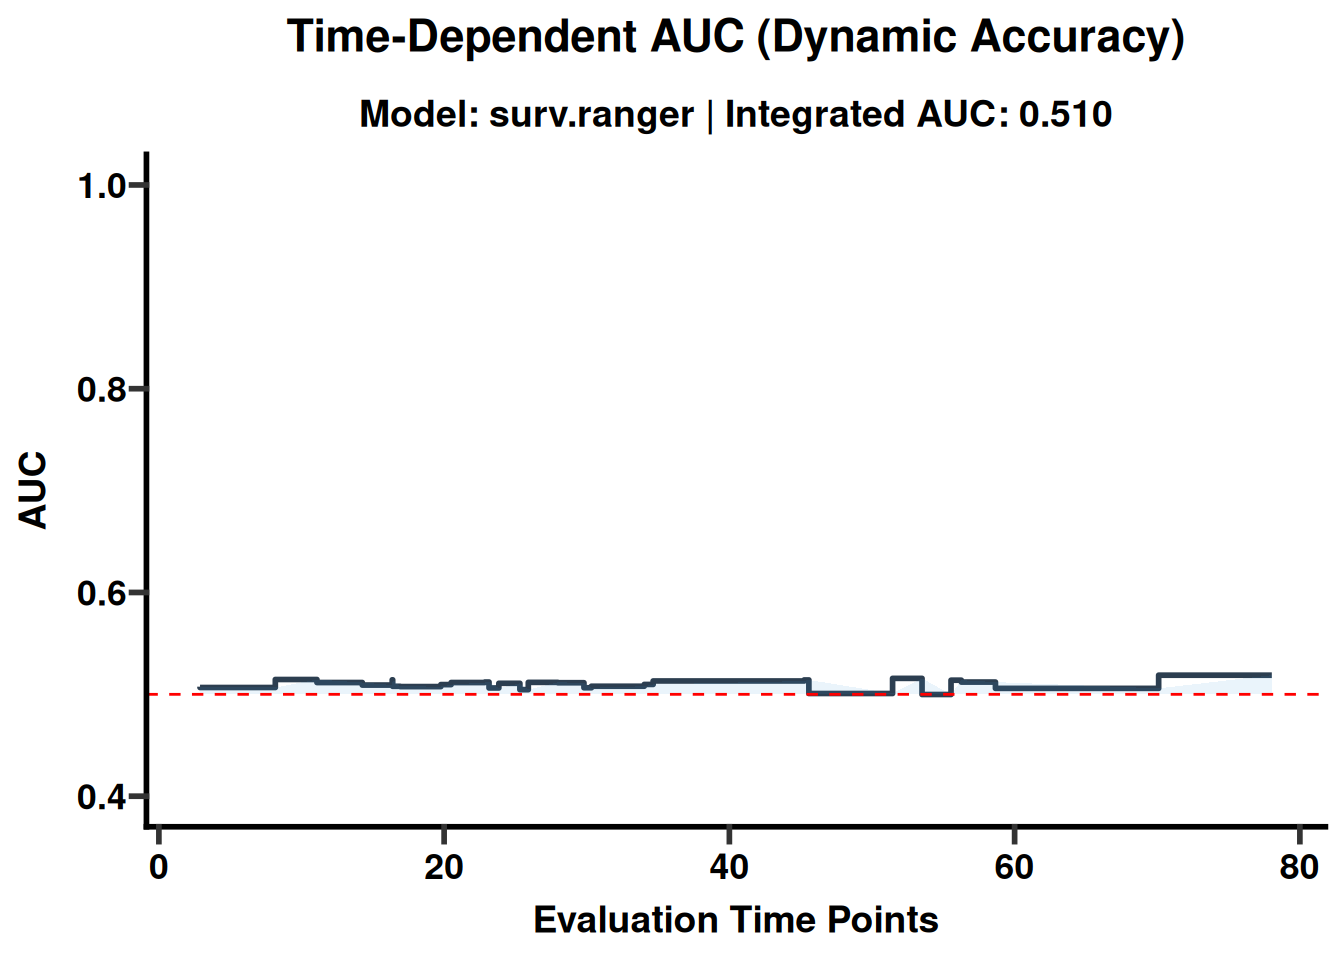
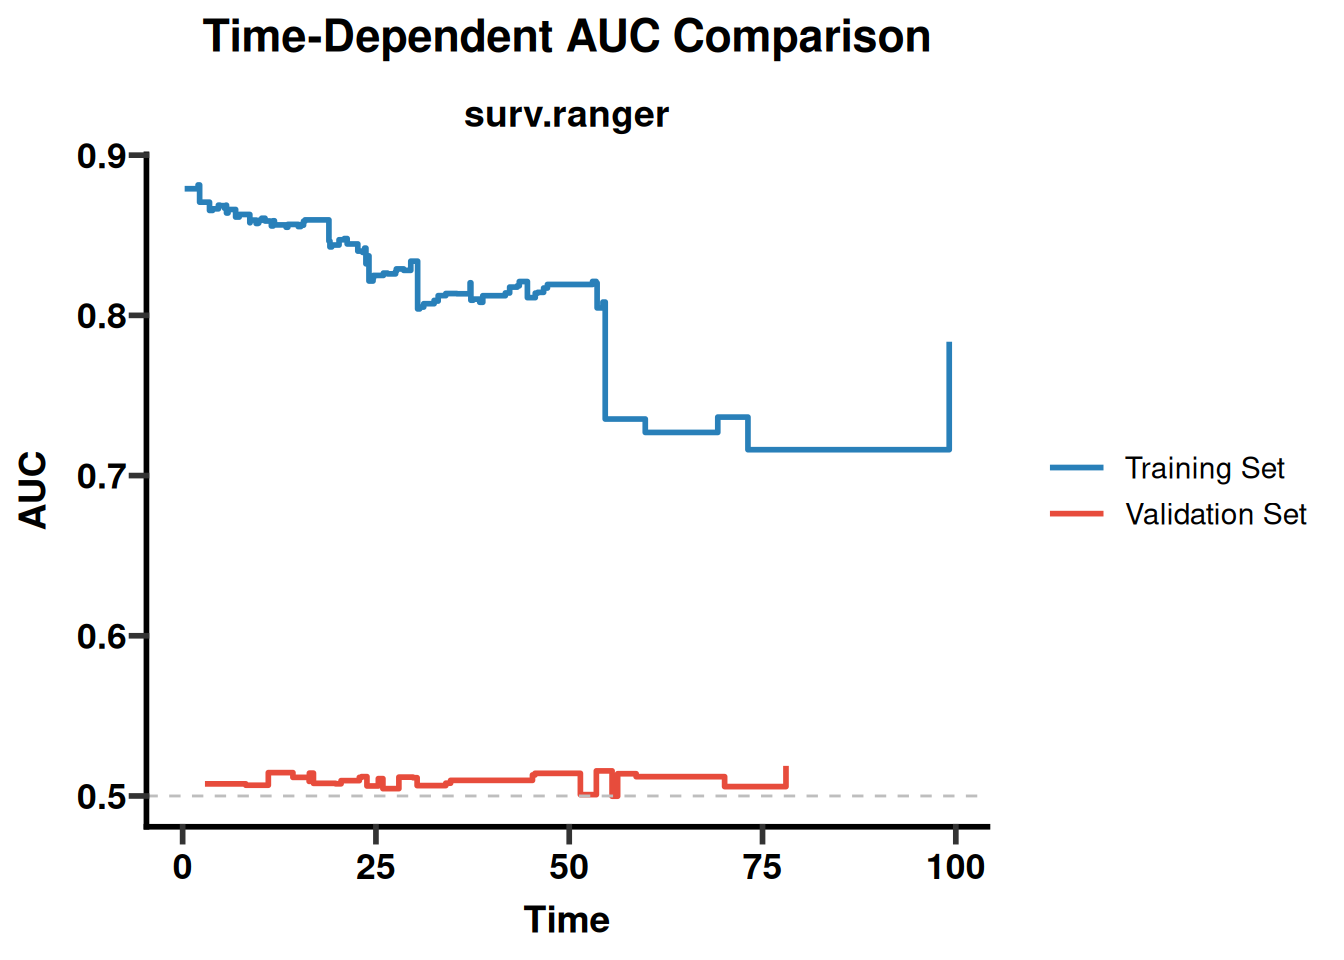
# ---- 4.3 Time‑dependent AUC (training vs validation) ----
auc_train <- surv_plot_time_dependent_auc(best_lrn, train_task)
auc_val   <- surv_plot_time_dependent_auc(best_lrn, val_task)
auc_cmp   <- surv_plot_comparison_auc(best_lrn, train_task, val_task)
ggsave(file.path(sub_dir("03_evaluation"), "AUC_comparison.pdf"), auc_cmp, width = 8, height = 5)

# ---- 4.4 Calibration curves (training vs validation) ----
cal_train <- surv_plot_calibration(best_lrn, train_task, time_point = 200)
cal_cmp <- surv_plot_comparison_calibration(best_lrn, train_task, val_task, time_point = 200)
ggsave(file.path(sub_dir("03_evaluation"), "Calibration_train.pdf"), cal_train, width = 8, height = 6)
ggsave(file.path(sub_dir("03_evaluation"), "Calibration_comparison.pdf"), cal_cmp, width = 8, height = 6)

# ---- 4.5 External validation (using the validation set) ----
val_data_ext <- as.data.frame(task_full$data())[val_idx, selected_feats, drop = FALSE]
val_data_ext$time <- task_full$data()[[task_full$target_names[1]]][val_idx]
val_data_ext$status <- task_full$data()[[task_full$target_names[2]]][val_idx]
val_res <- surv_predict_on_validation(best_lrn, val_data_ext, train_task)
val_cindex_alt <- val_res$prediction$score(msr("surv.cindex"))
cat("Validation C-index (alt):", round(val_cindex_alt, 4), "\n")
# ---- 4.6 Nomogram (with proportional hazards test) ----
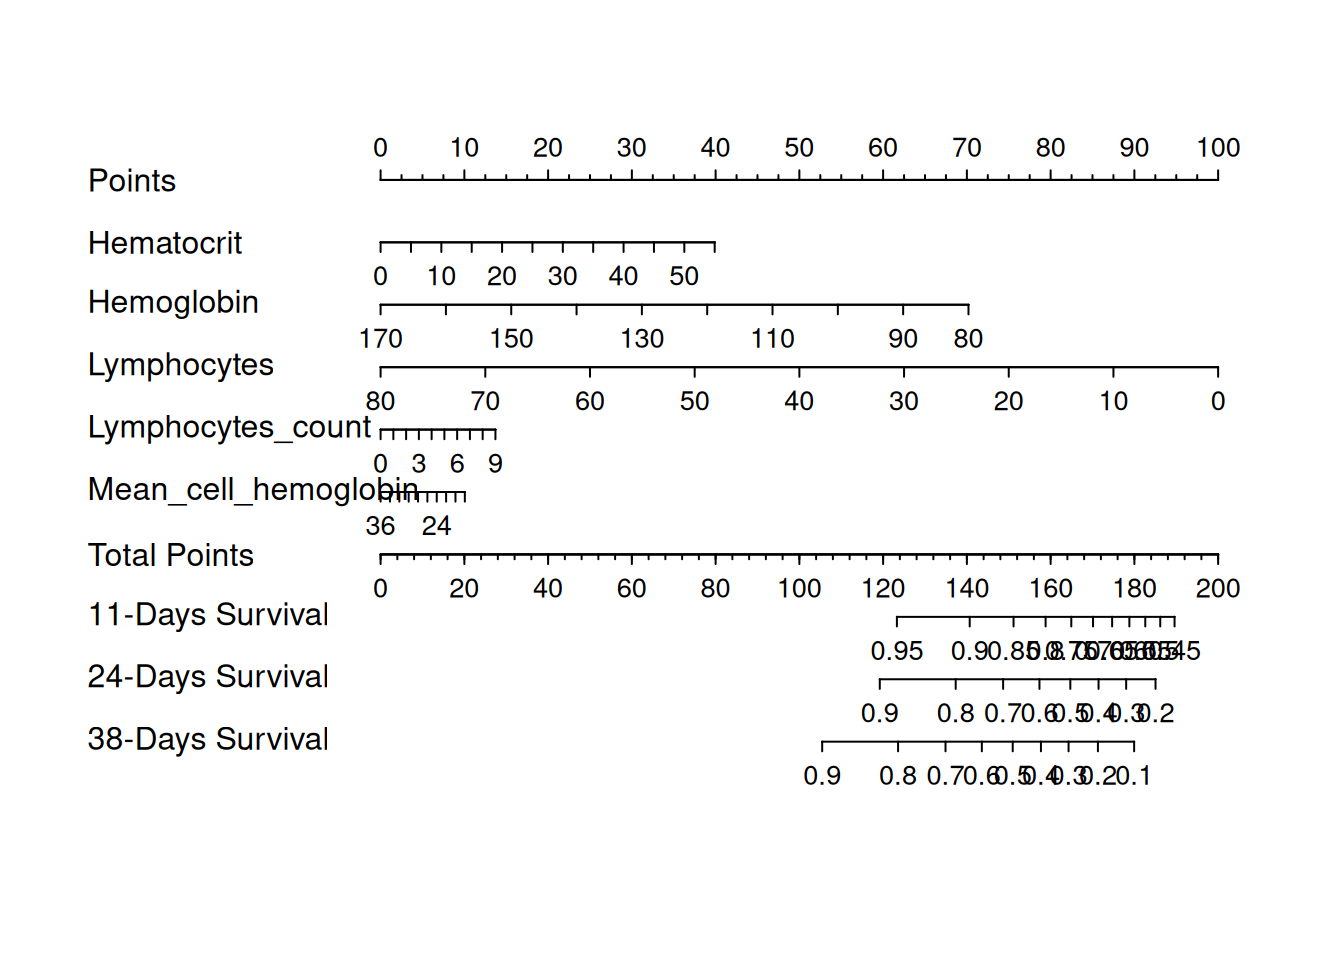
nom <- surv_generate_nomogram(train_task,
                              selected_features = head(selected_feats, 5),
                              time_points = c(90, 180, 365),
                              time_unit = "days")
# The nomogram plot is drawn; PH test results are printed to console.

# ---------------------------------------------------------------------------
````
### 5 Robustness analysis
This section tests sensitivity to sampling, censoring, and feature changes. Robust conclusions should remain similar under reasonable perturbations. It is run in three parts: feature stability, feature ablation, and model sensitivity.
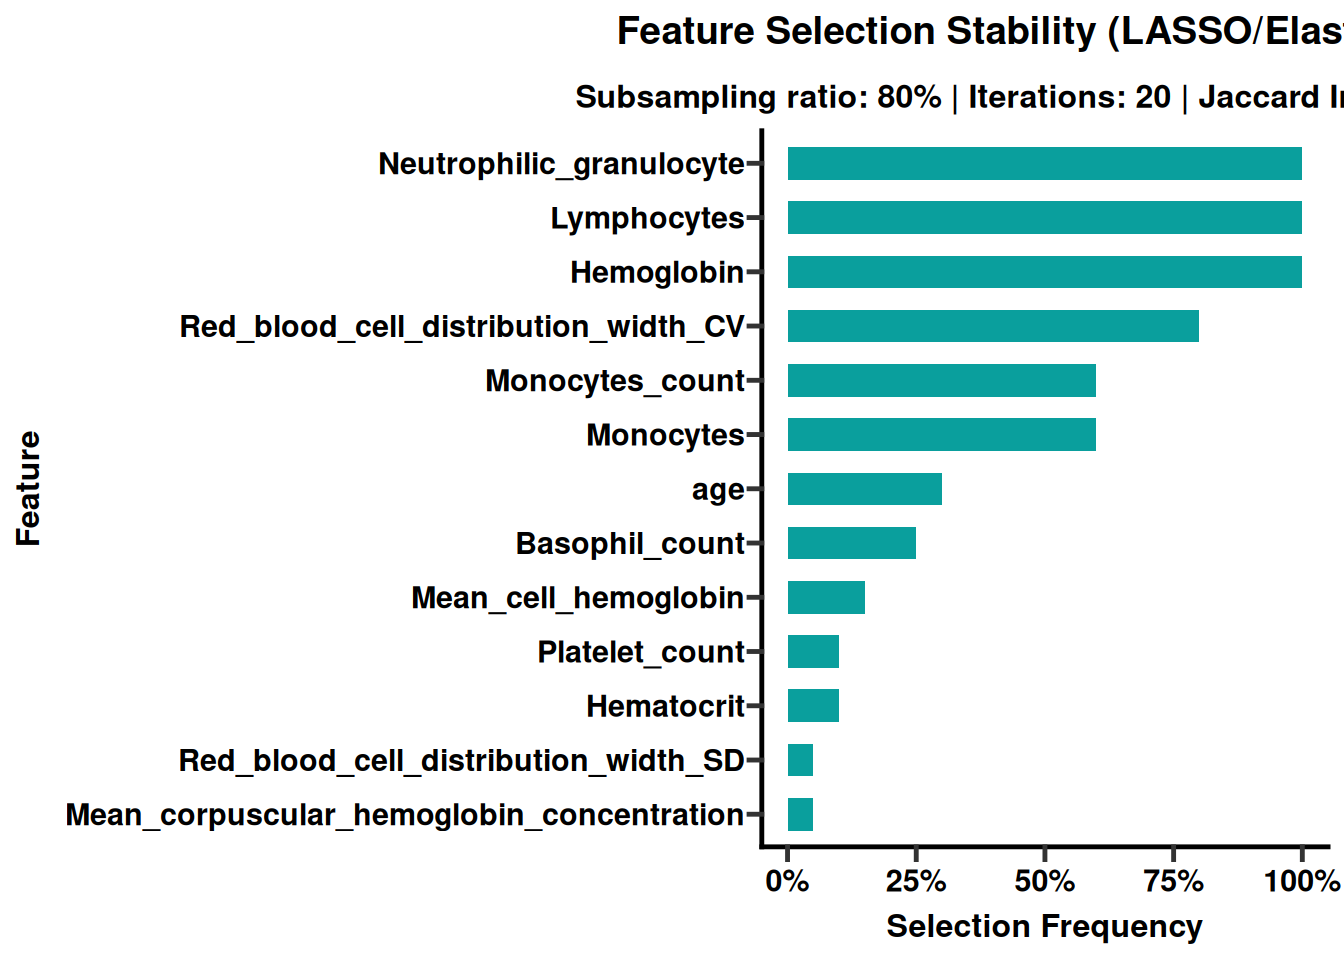
### 5.1 Feature stability (LASSO bootstrapping)
This section tests sensitivity to sampling, censoring, and feature changes. Robust conclusions should remain similar under reasonable perturbations.
````{r}
#| label: module4-pro-18
#| cache: false
#| echo: true
#| message: false
#| warning: false
#| fig-show: hold
#| out-width: '100%'
# 5.1 Feature stability (LASSO bootstrapping)
stab <- surv_analyze_feature_stability(train_task, "time", "status", n_repeat = 20, alpha = 1)
cat("Stability index:", round(stab$stability_index, 4), "\n")
ggsave(file.path(sub_dir("04_robustness"), "stability_plot.pdf"), stab$plot, width = 8, height = 6)
write.csv(stab$frequencies, file.path(sub_dir("04_robustness"), "stability_frequencies.csv"), row.names = FALSE)
````
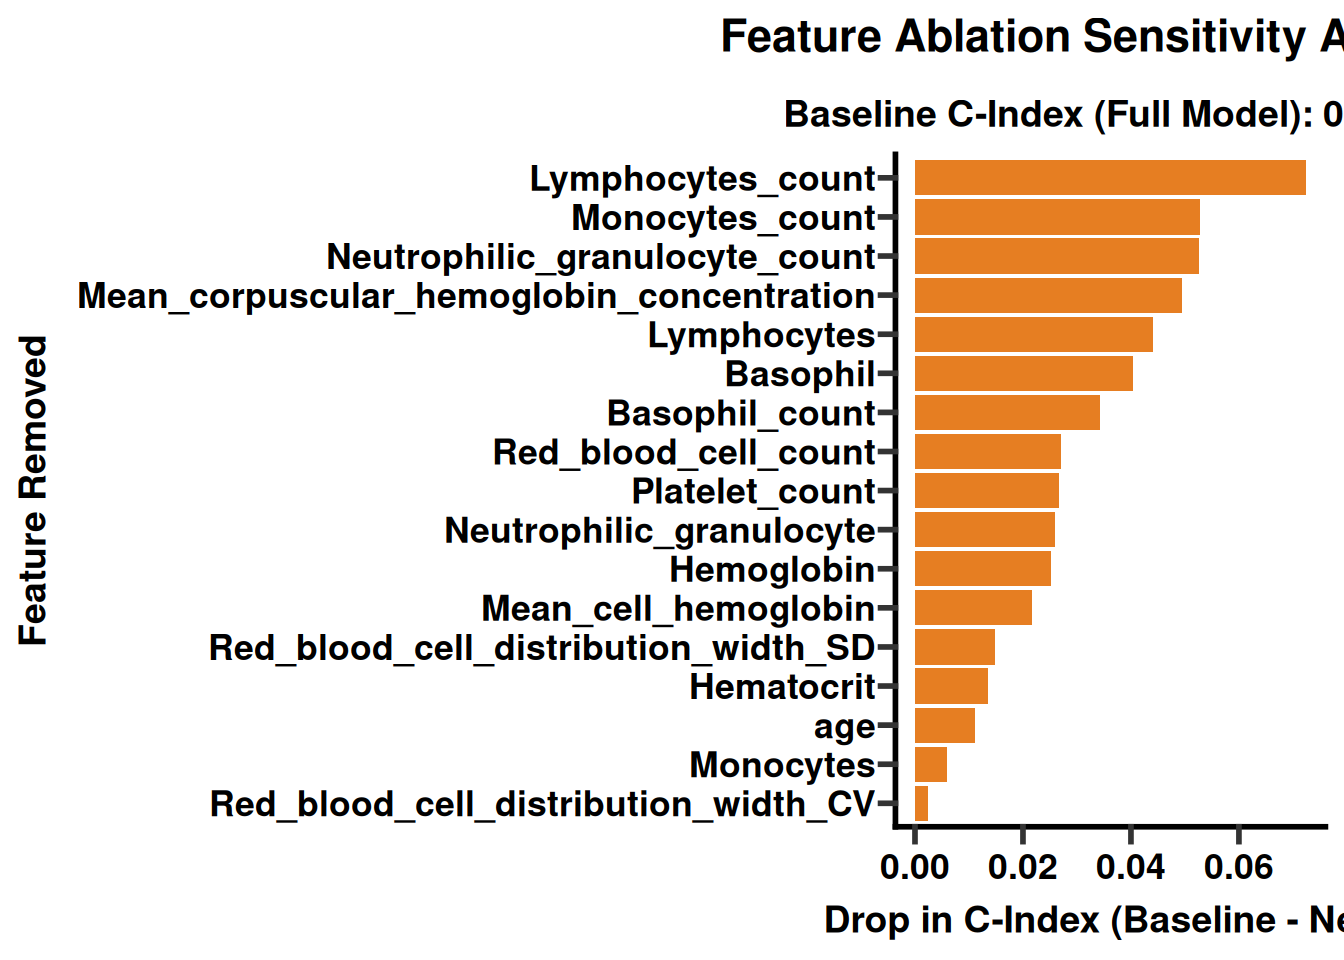
### 5.2 Feature ablation (drop each feature and measure C-index drop)
This section tests sensitivity to sampling, censoring, and feature changes. Robust conclusions should remain similar under reasonable perturbations.
````{r}
#| label: module4-pro-19
#| cache: false
#| echo: true
#| message: false
#| warning: false
#| fig-show: hold
#| out-width: '100%'
# 5.2 Feature ablation (drop each feature and measure C-index drop)
abl <- surv_analyze_feature_ablation(train_task, best_id, selected_feats)
ggsave(file.path(sub_dir("04_robustness"), "ablation_plot.pdf"), abl$plot, width = 8, height = 6)
write.csv(abl$results, file.path(sub_dir("04_robustness"), "ablation_results.csv"), row.names = FALSE)
````
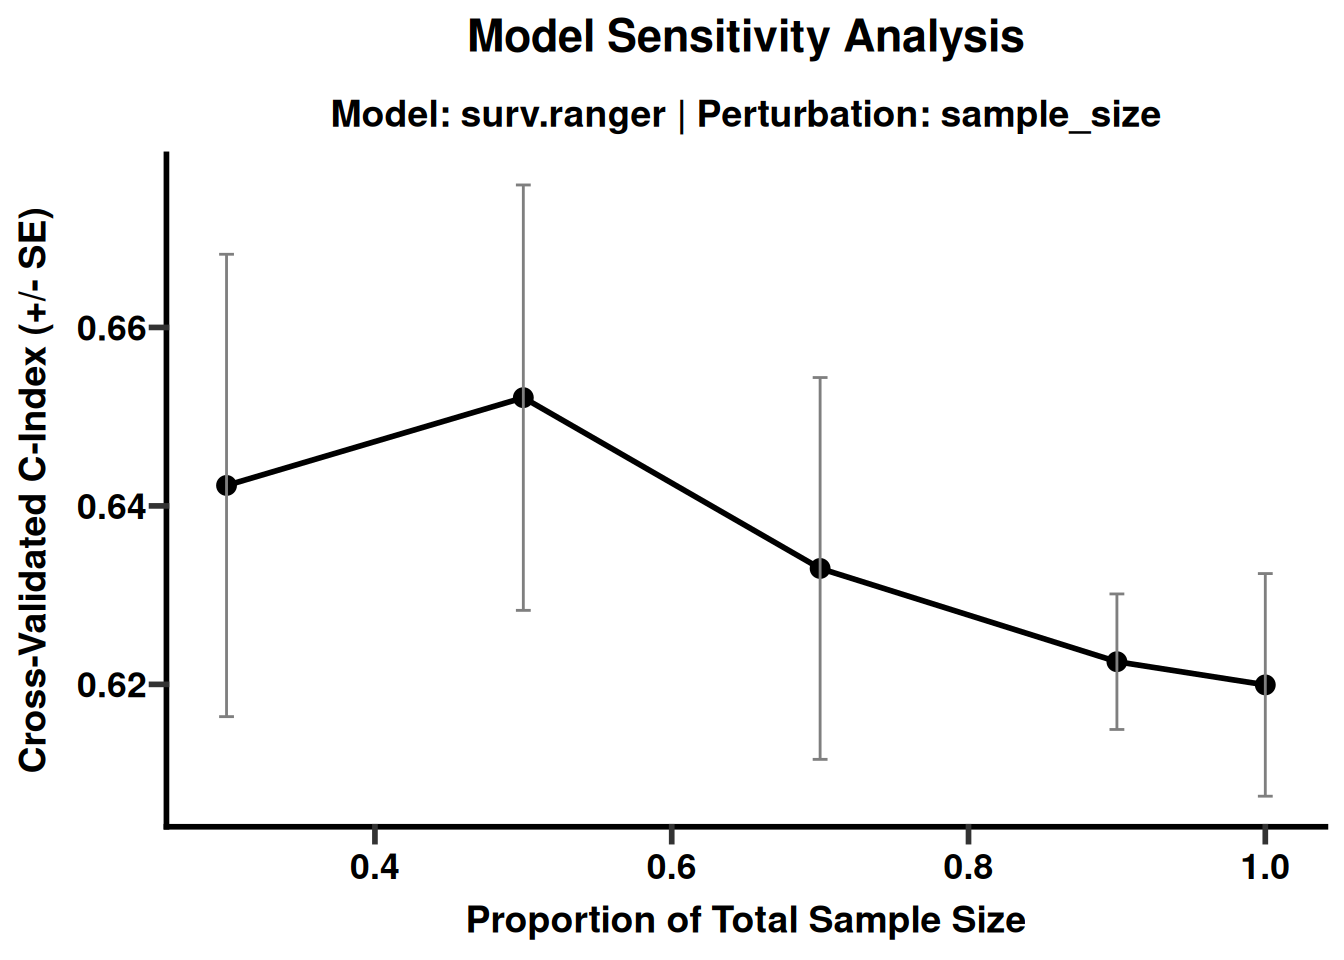
### 5.3 Model sensitivity (sample size and censoring rate)
This section trains and compares candidate models. Select models using discrimination, calibration, stability, and clinical utility together.
````{r}
#| label: module4-pro-20
#| cache: false
#| echo: true
#| message: false
#| warning: false
#| fig-show: hold
#| out-width: '100%'
# 5.3 Model sensitivity (sample size and censoring rate)
sens_sample <- surv_analyze_model_sensitivity(train_task, best_id, analysis_type = "sample_size")
sens_censor <- surv_analyze_model_sensitivity(train_task, best_id, analysis_type = "censoring")
ggsave(file.path(sub_dir("04_robustness"), "sensitivity_sample.pdf"), sens_sample$plot, width = 8, height = 5)
ggsave(file.path(sub_dir("04_robustness"), "sensitivity_censor.pdf"), sens_censor$plot, width = 8, height = 5)
write.csv(sens_sample$results, file.path(sub_dir("04_robustness"), "sensitivity_sample.csv"), row.names = FALSE)
write.csv(sens_censor$results, file.path(sub_dir("04_robustness"), "sensitivity_censor.csv"), row.names = FALSE)

# ---------------------------------------------------------------------------
````
### 6 Decision curve analysis (DCA) and SHAP explanations (on validation set)
This section examines clinical utility and model explanations. Explanatory plots describe model behavior and do not establish causality.
````{r}
#| label: module4-pro-21
#| cache: false
#| echo: true
#| message: false
#| warning: false
#| fig-show: hold
#| out-width: '100%'
# 6. Decision curve analysis (DCA) and SHAP explanations (on validation set)
# ---------------------------------------------------------------------------
# Determine a valid evaluation time from validation event times
val_time <- val_task$data()[[val_task$target_names[1]]]
val_status <- val_task$data()[[val_task$target_names[2]]]
event_times <- val_time[val_status == 1]
if (length(event_times) == 0) stop("No events in validation set.")
eval_time <- round(quantile(event_times, 0.5, na.rm = TRUE), 0)
if (eval_time < min(event_times)) eval_time <- min(event_times)
cat("Using eval_time =", eval_time, "for DCA\n")
# DCA
dca_res <- plot_dca_survival(
  learners = list("Tuned" = best_lrn),
  object = val_task,
  eval_time = eval_time,
  clin_range = c(0.05, 0.5),
  print_stats = TRUE
)
ggsave(file.path(sub_dir("05_xai"), "dca_plot.pdf"), dca_res$plot, width = 7, height = 5)
write.csv(dca_res$table, file.path(sub_dir("05_xai"), "dca_table.csv"), row.names = FALSE)

# Global SHAP (SurvSHAP(t))
shap_global <- surv_explain_shap(
  learner = best_lrn,
  task = val_task,
  type = "global",
  n_explain = 30,
  n_background = 10,
  n_timepoints = 10,
  n_top_features = 6,
  verbose = TRUE
)
ggsave(file.path(sub_dir("05_xai"), "shap_global_bar.pdf"), shap_global$plots$bar_plot, width = 8, height = 6)
if (!is.null(shap_global$plots$line_plot)) {
  ggsave(file.path(sub_dir("05_xai"), "shap_global_line.pdf"), shap_global$plots$line_plot, width = 8, height = 6)
}
write.csv(shap_global$shap_long, file.path(sub_dir("05_xai"), "shap_values_global.csv"), row.names = FALSE)

# Beeswarm plot
beeswarm_plot <- surv_plot_shap_beeswarm(shap_global, top_n = 6, method = "beeswarm",
                                         title = "Global SurvSHAP (validation set)")
ggsave(file.path(sub_dir("05_xai"), "shap_beeswarm.pdf"), beeswarm_plot, width = 9, height = 6)

# =============================================================================
````
### 7 Ten advanced extensions (all executed sequentially)
This section performs the core analysis for this stage. Review the output immediately below the code and confirm that data ranges, assumptions, and results match the study design.
````{r}
#| label: module4-pro-22
#| cache: false
#| echo: true
#| message: false
#| warning: false
#| fig-show: hold
#| out-width: '100%'
# 7. Ten advanced extensions (all executed sequentially)
# =============================================================================
cat("\n========== Running 10 advanced extensions ==========\n")
# ---- 7.1 Competing risks (Fine‑Gray or cause‑specific Cox) ----
# Purpose: Correctly estimate cumulative incidence when competing events exist.
# Method: Fine‑Gray via mlr3extralearners or cause‑specific Cox.
cat("\n--- 7.1 Competing risks (Fine‑Gray / cause‑specific Cox) ---\n")
if (requireNamespace("mlr3extralearners", quietly = TRUE)) {
  fg_res <- tryCatch({
    run_competing_risks(prog, model_type = "finegray", cause = 1, tuning_budget = 20)
  }, error = function(e) {
    cat("Competing risks failed:", e$message, "\n")
    NULL
  })
  if (!is.null(fg_res)) {
    cat("Fine‑Gray CV C-index:", round(fg_res$cv_cindex, 4), "\n")
    saveRDS(fg_res, file.path(sub_dir("05_xai"), "competing_risks.rds"))
  }
} else {
  cat("Skipping (mlr3extralearners not installed).\n")
}
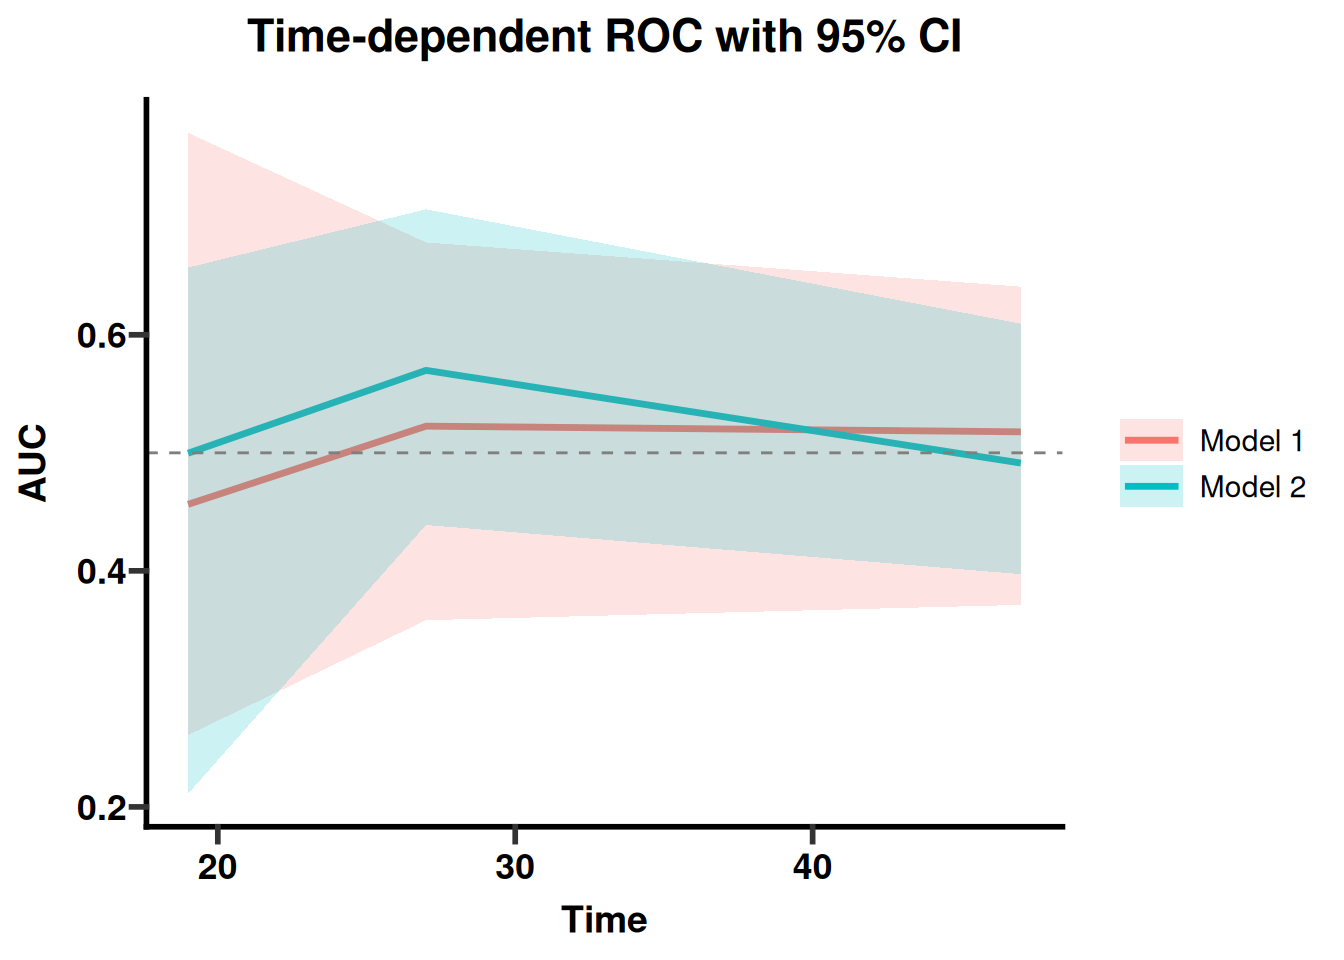
# ---- 7.2 Time‑dependent ROC comparison (Ranger vs Cox) ----
# Purpose: Compare AUC trajectories and obtain bootstrap confidence intervals.
# Method: timeROC with bootstrapping.
cat("\n--- 7.2 Time‑dependent ROC comparison (Ranger vs Cox) ---\n")
td_roc <- tryCatch({
  plot_tdROC_comparison(best_lrn, cox_lrn, val_task, n_boot = 50, save_plot = TRUE)
}, error = function(e) {
  cat("tdROC comparison failed:", e$message, "\n")
  NULL
})

# ---- 7.3 Multi‑time calibration curves ----
# Purpose: Assess calibration at multiple clinically relevant horizons.
# Method: Separate calibration plots at each time point, combined with patchwork.
cat("\n--- 7.3 Multi‑time calibration curves (90, 180, 365 days) ---\n")
tryCatch({
  plot_multitime_calibration(best_lrn, val_task, time_points = c(90, 180, 365), save_plot = TRUE)
}, error = function(e) {
  cat("Multi‑time calibration failed:", e$message, "\n")
})
# ---- 7.4 Repeated cross‑validation (with parallel support) ----
# Purpose: Obtain robust performance estimates with confidence intervals.
# Method: 5 repeats of 5‑fold CV, compute Bootstrap CI for C‑index.
cat("\n--- 7.4 Repeated cross‑validation (5×5‑fold CV) ---\n")
cv_res <- tryCatch({
  repeated_cv_evaluation(prog, "surv.ranger", n_repeats = 5, folds = 5, parallel = FALSE)
}, error = function(e) {
  cat("Repeated CV failed:", e$message, "\n")
  NULL
})
if (!is.null(cv_res)) {
  cat("Repeated CV summary:\n")
  print(cv_res$summary)
  write.csv(cv_res$results, file.path(sub_dir("04_robustness"), "repeated_cv_results.csv"), row.names = FALSE)
}
# ---- 7.5 DeLong test for comparing C‑indices ----
# Purpose: Statistically compare discriminative ability of Ranger vs Cox.
# Method: survcomp::cindex.comp (bootstrap‑based DeLong).
cat("\n--- 7.5 DeLong test (Ranger vs Cox) ---\n")
delong <- tryCatch({
  compare_models_delong(best_lrn, cox_lrn, val_task, n_boot = 500)
}, error = function(e) {
  cat("DeLong test failed:", e$message, "\n")
  NULL
})
if (!is.null(delong)) {
  cat("DeLong p‑value:", delong$p.value, "\n")
  cat("C‑index Ranger:", round(delong$C_index_model1, 4), "\n")
  cat("C‑index Cox:    ", round(delong$C_index_model2, 4), "\n")
  write.csv(data.frame(
    Model1_Cindex = delong$C_index_model1,
    Model2_Cindex = delong$C_index_model2,
    Difference = delong$difference,
    P_value = delong$p.value,
    CI_lower = delong$ci_lower,
    CI_upper = delong$ci_upper
  ), file.path(sub_dir("05_xai"), "delong_test.csv"), row.names = FALSE)
}
# ---- 7.6 Bayesian hyperparameter optimisation ----
# Purpose: More efficient search than random search, with automatic fallback.
# Method: mlr3mbo, falls back to random search on error.
cat("\n--- 7.6 Bayesian optimisation (Ranger) ---\n")
bayes_tune <- tryCatch({
  tune_with_bayes(train_task, "surv.ranger", tuning_budget = 30)
}, error = function(e) {
  cat("Bayesian optimisation failed:", e$message, "\n")
  NULL
})
if (!is.null(bayes_tune)) {
  saveRDS(bayes_tune, file.path(sub_dir("02_model"), "bayes_tune.rds"))
  cat("Bayesian tuned C‑index:", round(bayes_tune$cv_performance, 4), "\n")
}
# ---- 7.7 AIC stepwise variable selection ----
# Purpose: Complementary traditional feature selection using AIC.
# Method: MASS::stepAIC on a Cox model (bidirectional).
cat("\n--- 7.7 AIC stepwise selection (both directions) ---\n")
step <- tryCatch({
  stepwise_variable_selection(prog, direction = "both")
}, error = function(e) {
  cat("Stepwise selection failed:", e$message, "\n")
  NULL
})
if (!is.null(step)) {
  cat("Stepwise selected features:", paste(step$selected_features, collapse = ", "), "\n")
  write.csv(data.frame(Features = step$selected_features),
            file.path(sub_dir("01_feature_selection"), "stepwise_features.csv"), row.names = FALSE)
}
# ---- 7.8 Calibration‑in‑the‑large ----
# Purpose: Check overall calibration (mean predicted vs observed event rate).
# Method: Logistic regression of observed binary outcome on logit(predicted probability).
cat("\n--- 7.8 Calibration‑in‑the‑large (t = 365 days) ---\n")
cal_large <- tryCatch({
  calibration_in_the_large(best_lrn, val_task, time_point = 365)
}, error = function(e) {
  cat("Calibration‑in‑the‑large failed:", e$message, "\n")
  NULL
})
if (!is.null(cal_large)) {
  cat("Calibration intercept:", round(cal_large$intercept, 4), "\n")
  cat("Calibration slope:    ", round(cal_large$slope, 4), "\n")
  cat("Mean predicted:       ", round(cal_large$mean_predicted, 4), "\n")
  cat("Observed:             ", round(cal_large$observed, 4), "\n")
  write.csv(data.frame(
    Intercept = cal_large$intercept,
    Slope = cal_large$slope,
    Mean_Predicted = cal_large$mean_predicted,
    Observed = cal_large$observed,
    N_at_risk = cal_large$n_at_risk
  ), file.path(sub_dir("03_evaluation"), "calibration_large.csv"), row.names = FALSE)
}
# ---- 7.9 External validation (Hosmer‑Lemeshow test) ----
# Purpose: Assess calibration goodness‑of‑fit on validation set.
# Method: Group patients by predicted risk, compare observed vs expected events, χ² test.
cat("\n--- 7.9 Survival Hosmer‑Lemeshow test (t = 365 days, 10 groups) ---\n")
hl <- tryCatch({
  external_validation_test(best_lrn, val_task, time_point = 365, n_groups = 10)
}, error = function(e) {
  cat("HL test failed:", e$message, "\n")
  NULL
})
if (!is.null(hl)) {
  cat("HL chi‑square:", round(hl$chi_square, 4), "df:", hl$df, "p‑value:", round(hl$p_value, 4), "\n")
  write.csv(data.frame(
    Chi_square = hl$chi_square,
    df = hl$df,
    P_value = hl$p_value,
    N_total = hl$n_total
  ), file.path(sub_dir("03_evaluation"), "hl_test.csv"), row.names = FALSE)
}

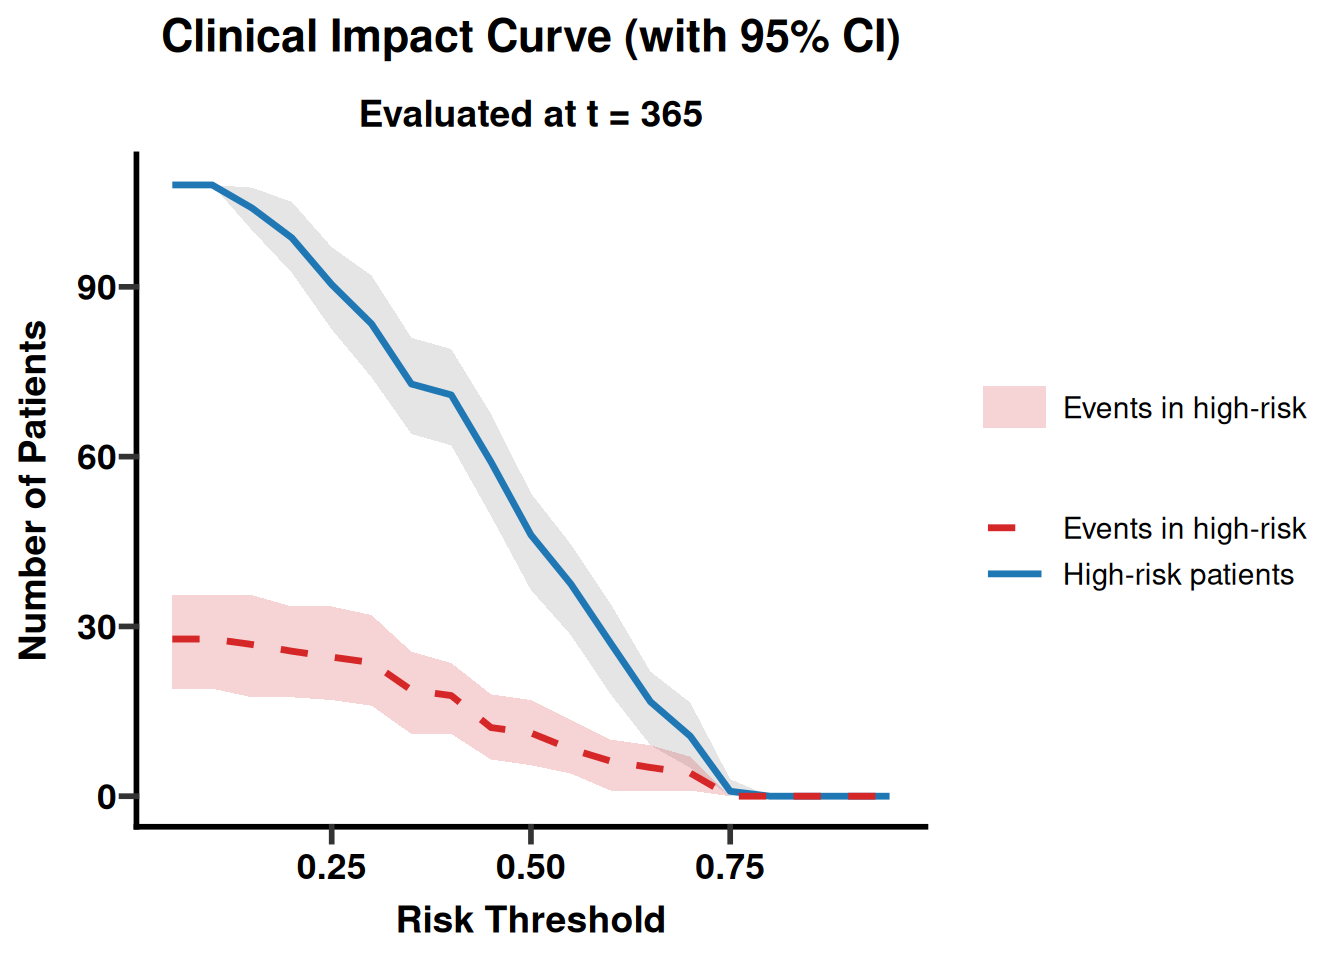
# ---- 7.10 Clinical impact curve ----
# Purpose: Show number of high‑risk patients and events across thresholds.
# Method: Bootstrap confidence bands for both curves.
cat("\n--- 7.10 Clinical impact curve (t = 365 days) ---\n")
tryCatch({
  plot_clinical_impact(best_lrn, val_task, time_point = 365, n_boot = 100, save_plot = TRUE)
}, error = function(e) {
  cat("Clinical impact curve failed:", e$message, "\n")
})

cat("\n========== All advanced extensions completed ==========\n")
# ---------------------------------------------------------------------------
````
### 8 Save final PrognosiX object and deploy
This section applies the trained object to new samples. Validate input format, performance, and target population in an independent cohort before deployment.
````{r}
#| label: module4-pro-23
#| cache: false
#| echo: true
#| message: false
#| warning: false
#| fig-show: hold
#| out-width: '100%'
# 8. Save final PrognosiX object and deploy
# ---------------------------------------------------------------------------
prog@best.model <- list(
  learner_id = best_id,
  learner = best_lrn,
  best_params = tune$best_params,
  cv_cindex = cv_cindex,
  features = selected_feats,
  cutoff = opt_cutoff,
  decision_type = "binary",
  train_cols = train_task$feature_names
)
prog@subgroup.risk <- list(
  benchmark_table = bmr1$table,
  stability = stab,
  ablation = abl,
  validation = list(cindex = val_cindex, n = val_task$nrow)
)
prog@split.data <- list(train_idx = train_idx, val_idx = val_idx)
saveRDS(prog, file = file.path(sub_dir("data"), "prog_obj_final.rds"))

# ---- 8.1 Predict risk for new patients ----
#new_patients <- data.frame(
#  Mean_corpuscular_hemoglobin_concentration = c(33, 34),
#  Basophil_count = c(0.02, 0.03),
#  Monocytes = c(0.6, 0.7),
#  Eosinophil_count=c(0.02, 0.03),
#  Basophil=c(0.6, 0.7),
#  Neutrophilic_granulocyte = c(4.2, 5.1),
#  Red_blood_cell_distribution_width_CV = c(12.3, 11.8),
#  Mean_red_blood_cell_volume = c(89, 92),
#  Lymphocytes_count = c(1.8, 2.1),
#  Platelet_volume_distribution_width = c(12.0, 13.1),
#  Lymphocytes = c(1.8, 2.1),
#  Monocytes_count = c(0.6, 0.7),
#  Neutrophilic_granulocyte_count = c(4.2, 5.1),
#  Mean_platelet_volume = c(10.5, 11.0),
#  row.names = c("patient_1", "patient_2")
#)

#risk_scores <- predict_prognosix(prog, new_patients, impute = TRUE)
#pred_groups_med <- predict_risk_groups(prog, new_patients, cutoff_method = "median")
#pred_groups_cus <- predict_risk_groups(prog, new_patients,
#                                       cutoff_method = "custom",
#                                       custom_cutoffs = opt_cutoff)
#cat("Risk scores:\n"); print(risk_scores)
#cat("Median groups:\n"); print(pred_groups_med)
#cat("Custom groups:\n"); print(pred_groups_cus)

# ---- 8.2 Deployment manager and Shiny app ----
manager <- New_Prog_Manager(prog)
if (interactive()) {
  use_app_theme_grey()
  set_prog_app_text(
    title = "Survival Risk Predictor",
    citation_text = "Data: PMID37633276_DIA_plasmaproomic cohort."
  )
  set_prog_app_theme(
    primary_color = "#2c7fb8", background_color = "#f0f4f8", sidebar_color = "#e9ecef",
    box_background = "#ffffff", label_color = "#2c7fb8",
    run_button_gradient_start = "#2c7fb8", run_button_gradient_end = "#1d4e6e",
    risk_high_color = "#d9534f", risk_medium_color = "#f0ad4e", risk_low_color = "#5cb85c",
    table_header_color = "#2c7fb8", font_family = "Arial, sans-serif", font_size_base = 14
  )
  launch_prog_deploy_app(
    manager,
    var_dict = data.frame(
      Feature = selected_feats,
      Description = paste("Predictor", seq_along(selected_feats)),
      Units = rep("--", length(selected_feats))
    ),
    project_info = list(
      abstract = paste("Prognostic model trained on", train_task$nrow, "patients."),
      citation = "PMID37633276_DIA_plasmaproomic cohort."
    )
  )
}

# ---------------------------------------------------------------------------
````
### 9 Final report
This section saves model objects, tables, and figures for reproducibility, review, and reuse.
````{r}
#| label: module4-pro-24
#| cache: false
#| echo: true
#| message: false
#| warning: false
#| fig-show: hold
#| out-width: '100%'
# 9. Final report
# ---------------------------------------------------------------------------
cat("\n========================================\n")
cat("Module 4 (advanced, leakage‑free) finished successfully!\n")
cat("Best model:", best_id,
    "| CV C-index (training):", round(cv_cindex, 4),
    "| Validation C-index:", round(val_cindex, 4), "\n")
cat("Optimal cutoff:", round(opt_cutoff, 4), "\n")
cat("All results saved under:", OUTPUT_DIR, "\n")
cat("========================================\n")
````